$ ssh cse29.ucsd.edu
Password:

   ___________ ______ ___   ____
  / ____/ ___// ____/|__ \ / __ \
 / /    \__ \/ __/   __/ // /_/ /
/ /___ ___/ / /___  / __/ \__, /
\____//____/_____/ /____//____/

$ ./letsgo
Initalizating I/O...
Making Memories...
Setting up HTTP server...
Checking password hashes....
Reticulating splines...
UCSD CSE29 FA26 Syllabus and Logistics
Aaron Schulman (Shalev) (Instructor)
CSE 29 introduces you to the broad field of systems programming, including 1) the basics of how programs execute on a computer, 2) programming in C with direct access to memory and system calls, 3) software tools to manage and interact with code and programs. All very cool stuff that makes every programmer better!
Basics
- Lecture:
- Mon/Wed/Fri 3:00-3:50pm, Warren Lecture Hall 2001
- Discussion:
- Wednesday 6:00-6:50pm, Galbraith Hall 242
- Labs: Tuesdays (check your schedule!). Either B240 or B250 in the CSE building
- Exams:
- Weeks 4, 8, and 10: During your regularly-scheduled lab time
- Finals week: In CSE labs, scheduling instructions coming soon!
- Professor office hours (these are the standard times but check the calendar below for changes!)
- Wednesday 1:00-2:00pm CSE B270/tables outside labs (CSE29 students only)
- Thursday 2:30-3:30pm, CSE 3206 (advising focused, open to all students)
- Office Hours: Refer to calendar
- Q&A forum: Piazza
- PrairieLearn: https://us.prairielearn.com
- Textbook/readings: Dive Into Systems, plus additional readings we will assign
- Free: MIT Missing Semester
- Not free but pretty cheap: Julia Evans Zines, especially The Pocket Guide to Debugging
- Reference Sheets: Google Doc
- Lecture Review Template (for late submissions): Review Template
Office Hours Calendar
Schedule
-
Week 7 – Dynamic Memory Allocation
- Lecture Materials
- Monday
- Code: mm.c
- Review Questions Answers
- Monday
- Lecture Materials
-
Week 6 – OS Concepts
- Lecture Materials
- Monday
- Wednesday
- Lecture Materials
-
Week 5 – Structs and Malloc
- Lecture Materials
- Monday
- Wednesday
- Code: varstr.c
- Discussion (Code: 01_copy_struct.c, 02_struct.c, 03_decay.c)
- Code: Review Questions
- Review Questions Answers
- Friday
- Code: varstr.c
- Code: Review Questions
- Review Questions Answers
- Lecture Materials
-
Week 4 – System Calls
- Lecture Materials
- Monday
- Wednesday
- Code: strtok.c
- Code: shell.c
- Discussion
- Friday
- Code: shell.c
- Code: vm.c
- Review Questions Answers
- Lecture Materials
-
Week 3 – Pointers
- Lecture Materials
- Monday
- Wednesday
- Lecture
- Code: hash.c
- Review Questions Answers
- Discussion (Code: sizeof.c)
- Friday
- Lecture
- Code: stack_demo.c
- Code: vector_sum.c
- Review Questions Answers
- Lecture Materials
-
Week 2 – UTF-8 and Shell
- Lecture Materials
- Monday
- Wednesday
- Review Questions: REVIEW.txt
- Code: arrays.c, webserver.c
- Review Questions Answers
- Discussion (Code: utf8analyzer.c)
- Friday
- Lecture Materials
-
Week 1 – Binary, Printing, and Strings
- Lecture Materials
- Monday
- Wednesday
- Friday
- Lecture
- Code: uppercase.c
- Code: is_multibyte.c
- Lecture Materials
-
Week 0 – Welcome, Strings and Bitwise Representations
- Lecture Materials
- Friday
- Lecture Materials
Course Components
There are three main parts of the course: Assignments, Exams, and Social Learning.
Assignments
The course has 5 assignments that involve programming and writing. For each there will be:
- A problem set that has practice problems related to the assignment
- A programming project where you create a program that does something interesting and that we automatically test
- Design questions about the programming project
Grading: There are 6 points available for each assignment.
- 2 points for the corresponding problem set (2 points for fully correct and complete by the deadline, 1 point for somewhat complete at the deadline, 0 points for incomplete or very little completed at the deadline).
- 2 points for program correctness (2 points for perfect or nearly-perfect, 1 point for significant errors, 0 for programs that work on very few or no examples)
- 2 points for design questions (2 points for perfect or nearly-perfect, 1 point for minor errors, 0 points for major errors or incomplete)
After each assignment is graded, you’ll have a chance to resubmit all components based on the feedback you received, which will detail what you need to do to increase your score. You can increase your score by up to 1 point in each component on a resubmit.
This is also the only late policy for assignments. Unsubmitted assignments are initially given a 0, and can get a maximum of 3 points on resubmission.
Exams
There will be 3 exams during the quarter and retake and make-up opportunities in finals week. The 3 exams will be held during labs in weeks 4, 8, and 10. We will provide a schedule for finals week where you can come in for retakes and makeups.
No study aids or devices are allowed to be used during the exams. You will need only a photo ID and something to write with (scratch paper is available on request).
The exams will be administered through PrairieLearn and PrairieTest. The exams will have a mix of questions; they will typically include some that involve programming and interacting with a terminal.
Exams are (necessarily) cumulative. They typically focus on content that has already had a due date (e.g. PAs, problem sets, design questions, and labs that have their work due before the exam period starts), and typically don’t focus on specific details only found in textbook chapters or mentioned conversationally in lecture. However, that’s only a statement about the overall design, not a hard constraint: we will never promise that course content from any particular week, lecture, assignment, textbook chapter, or other course component won’t appear on an exam. We say this publicly in the syllabus to avoid misunderstandings (“the professor/TA/my friend told me not to study that”) and to make it clear that all the content matters (we wouldn’t assign it if it didn’t).
Social Learning
Learning (in college) is in part, a social process. Your engagement with it forms part of your grade for the class.
Lecture (Social Learning)
Lectures are designed to introduce you to concepts, show how experts in systems design approach problems, and give you a chance to ask questions about content, connect course content to the world outside the classroom, talk to your classmates and the staff, and provide an overarching story for the material.
Most lectures will come with two on-paper activities that are handed in for credit:
- A review check, near the beginning of class. These serve mainly as a way to check in on content from previous lectures before starting the content for the day, and for us to get some information about how everyone is following along with lecture content. Don’t think of them as quizzes, rather as an engagement check. You can discuss these with your classmates, and they are graded on completeness rather than correctness.
We say these will happen in “most” lectures because sometimes we may skip one or both for various timing or logistics reasons.
Grading: Each lecture has 2 social learning points available:
- 2 for the review check (only 1 point if handed in but incomplete)
If you miss either or both during class, you can submit the makeup assignment later for 1 point total. This is the only way to make up credit for missing a lecture.
The makeup assignment requires you to finish the review check, regardless of whether you turned one in during class. So:
- If you only hand in one during class, you can submit the full makeup assignment to earn 1/2 points for that day.
- If you miss lecture entirely, you can submit the full makeup assignment to earn 1 point.
All resubmissions must be before the next lecture to count, with no exceptions.
Labs (Social Learning)
The course’s lab component meets for 2 hours. In each lab you’ll switch between working on your own, working in pairs, and participating in group discussions about your approach, lessons learned, programming problems, and so on.
The lab sessions and groups will be led by TAs and tutors, who will note your participation in these discussions for credit. Note that you must participate, not merely attend, for credit.
Grading: For each lab there are 4 possible points to earn:
- 1 for being present
- 2 for being an active, professional, productive participant while present
- 1 for submitting and/or getting work checked off that was done in lab
If you miss lab, you can earn the submission/check-off point by submitting the check off work before the next Monday (day before the labs) at 11am, but cannot earn the 3 points related to participation. There is no way to make up a lab beyond this 1 point, even for illness, travel, or emergencies. Our preference would be to require all 10 labs for an A, and have some kind of excused absences. However, tracking excused absences doesn’t really scale, so this policy is how we handle it.
Discussions (Social Learning)
There are discussions on Wednesday, led by the course staff, for going over problem set problems and the programming assignments.
Grading: Attendance is taken, and attending discussion gives 1 social learning point.
Grading
Each component of the course has a minimum achievement level to get an A, B, or C in the course. You must reach that achievement level in all of the categories to get an A, B, or C.
- A achievement:
- ≥85 social learning points (may adjust depending on the total number of available lecture points)
- ≥27/30 assignment points (≥90%)
- ≥10/12 exam points (≥83.3%)
- B achievement:
- 70-84 social learning points
- 23-26/30 assignment points (76.7-86.7%)
- 8-9/12 exam points (66.7-75%)
- C achievement:
- 55-69 social learning points
- 20-23/30 assignment points (66.7-76.7%)
- 6-7/12 exam points (50-58.3%)
Below C achievement (in any category) is an F/No Pass.
Pluses and minuses will be given based on performance on social learning and assignments (exam grades will not be used to determine plus and minus grades; this is to avoid extra load on retake testing). We don’t publish the exact cutoffs in advance.
Requests to change this grading policy (for a specific student or class-wide) will be denied with a link to this syllabus section. Consider this: we may, as instructors, decide for academic reasons that the most accurate way of assigning letter grades in the class needs to change (and we tend to only make changes that improve letter grades relative to this starting policy). However, it would be inappropriate for us to do so in response to student requests: that could create an appearance that we give students the grades they ask for rather than the grades they earned.
Policies and Perspective
CSE29, Large Language Models, and You
Evidence suggests that experts can generate (some kinds of) programs more quickly with the assistance of large language models. But, they did not become experts by using them.
We offer the following metaphor as guidance:
Consider physical conditioning, let’s take running for fitness in particular. There are many machines in the world that are remarkably effective at moving people around: electric scooters for example. Taking a scooter for a few miles gets you to your destination more quickly and less sweatily than running, but completely misses the point of the run. The goal of running for fitness has little to do with getting to a destination and everything to do with the changes that happen inside your body. Many people can run the same miles on the same road and get the benefits from it, despite them all doing the same work that a machine (the scooter) could have done.
Fitness is just one example like this. Similar comparisons make sense for learning to play an instrument, perform onstage, or upskill at games like billiards, darts, or Fortnite.
The programming in this class is like running for fitness (doing the typing and thinking on your own), not about getting to a destination quickly (handing in a completed program). The answers to many programming problems are known, or close-to-known, and many tools exist that can generate part or all of them, and there are many people who can write them faster than you. We assign the work not because knowing a solution is particularly important, but because the act of creating the solution changes you.
So, you should not use AI to generate code or prose for work in this class.
That said, it’s relatively difficult for us to detect AI usage on take-home work. It’s also useful to know what AI and code generation can do. So feel free to experiment, and do not read this policy as prohibiting, or assigning formal consequences to LLM use. A good way to go about learning in this course is to do the work yourself first, then go back and see how the LLM would have done it. Then you may be able to notice things, like the LLM generating extra unnecessary code, or doing something in a more or less complex way than you did it, or maybe doing exactly what you did! The key thing is that you developed a sense of what a solution was supposed to look like, rather than trusting the version from the machine.
(Also, the exams require that you program on your own, without the aid of any AI assistants.)
Device Policy
To a large degree, you are responsible for managing your time, attention, and learning in lecture, and I hesitate to make policies that attempt to govern or restrict your choices with respect to note taking or device use. However, lecture is a communal space, and your actions can affect others’ learning. In particular, what you have on your screen may be unavoidably in the field of view of other students. Because of this, you are responsible for a fragment of the attention of everyone in a cone of space behind you. With this in mind, the policy for lecture is that if you use a device, you must have lecture-related content onscreen. There is even research that shows that the content of screens in the classroom, even quite far away, can have a detrimental effect on learning. If you cannot resist checking social media, playing a game, or doing other off-topic tasks during lecture, sit in the back 2 rows so that you are only having an effect on your own attention, or the attention of others with a similar mindset.
Assignments and Academic Integrity
You can use code that we provide or that your group develops in lab as part of
your assignment. If you use code that you developed with other students (whether
in lab or outside it), got from Piazza, or got from the internet, say which
students you worked with and a sentence or two about what you did together in
CREDITS.txt. All of the writing in assignments (e.g. in open-ended written
questions) must be your own.
You can use an AI assistant like ChatGPT or Copilot to help you author
assignments in this class. If you do, you are required to include in
CREDITS.txt:
- The prompts you gave to the AI chat, or the context in which you used Copilot autocomplete
- What its output was and how you changed the output after it was produced (if at all)
This helps us all learn how these new, powerful, and little-understood tools work (and don’t).
If you don’t include a CREDITS.txt and it’s clear you included code from
others or from an AI tool, you may lose credit or get a 0 on the assignment, and
repeated or severe violations can be escalated to reports of academic integrity
violations.
Exams and Academic Integrity
It is a violation of academic integrity to share details of your exam with others until after you receive your grade for it. Keep in mind that the exams are randomized to discourage casual cheating, so your exam may not be the same one that others see. It is a violation of academic integrity to communicate with anyone other than the official proctors during the exam, or to use devices other than the ones you are using to complete the exam.
Lab and Professionalism
Lab work will be highly collaborative, and designed to encourage communication between students. Some of the activities will have you talk to other students, or exchange code, ideas, or commands with other students, and write down what happened.
In all of this communication, remember to be polite, professional, and focus on the work. A huge part of the job of a working software professional or researcher is professional and clear communication.
Some tricks for this: avoid statements that reference the author of the code, frame negative feedback as possible improvements or ways your expectations were violated, and take responsibility for anything you don’t understand.
Examples:
- Don’t say “You made a mistake here: …” Instead say “On line I expect the condition to be true but I think it will be false because XYZ … we could demonstrate that by doing ABC.”
- Don’t say “It seems like you don’t know about…”, instead say “On line
10-12, these 3 lines could be shortened into one line using
grep -rinstead offindfollowed bygrep: ….” And use some judgment: it’s likely that some of this advice is helpful and constructive, and some of it is just showing off. - Don’t say “This code is (going to be) slow…” Instead wait until you can run it and try an example that demonstrates it “This code took 10 seconds to run for input XYZ and that seems like a lot. When we were writing … I think I noticed that we did X, if we did Y instead I think it will go faster
- Don’t say “That conditional is ugly:…” Instead say “I find it easier to read these conditions when they are written as …. because …” If you don’t have a good explanation to put after the “because”, how do you know it’s a good suggestion? Refer also to the advice about not showing off
- Don’t say “You wrote lines 20-24 very confusingly.” Instead say “I’m having trouble understanding lines 20-24. It would help me to work through an example of how that part is supposed to work”
FAQ/AFQ (Anticipated Frequent Questions)
Q: I am waitlisted for one of the sections at position N. What should I do?
Come to class and do all the work as usual (you will have Canvas access to get all the needed links) so you can be up to speed if you do get a spot. This is aligned with official department policy.
We can’t make accurate predictions about chances of getting into the course from a specific waitlist position, or control that process as instructors.
Can I attend a lab section other than the one I’m enrolled in?
No, please do not try to do this. The lab sections have limited seating and are full. We cannot accommodate switching.
How can I switch sections?
You have to drop and re-add (which may involve getting [back on] the waitlist). Sorry.
Can I leave lab early if I’m done or have a conflict?
The labs are designed to not be things you can “finish”. Labs have plenty of extension and exploration activities at the end for you to try out, discuss, and help one another with. Co-located time with other folks learning the same things is precious and what courses are for. Also, if you need an extrinsic motivation, you won’t get credit for participation if you don’t stay, and participate, the whole time. We can often accommodate one-off exceptions – if you have a particular day where you need to leave early, it’s a good idea to be extra-engaged in your participation so your lab leader can give you participation credit before you leave.
Do I have to come to lab?
Yes, see grading above.
I missed lab, what should I do?
The lab page will have instructions on how to submit the make-up, which can get you 1 (of 4 possible) points.
I missed my exam time, what should I do?
Stay tuned for announcements about scheduling make-ups in final exam week.
Where is the financial aid survey?
We do this for you; as long as you submit something in the first two weeks, we will mark you as commencing academic activity.
I have a conflict with the final exam time, what can I do?
The final exam week we will offer flexibly scheduled timeslots to retake the three PrarieLearn exams from the quarter.
Lab Resources
Hello there.
As each lab is a mix of information and activities, it can become a lot to look through to find a particular piece of information. Here I have provided pointers to pieces of labs describing how to use particular software tools.
Lab 1: Unix, SSH, and Vim
Welcome to the first CSE 29 lab!
Lab is the time and space to explore practical software tools aspect of CSE 29’s title. Tools will include Unix commands, Git, GDB, Valgrind, Makefiles, shell scripting, and more.
You are not expected to know what any of these topics are yet—this is just a preview of what’s to come. Over the next 10 weeks, the lab writeups found here will guide you as you build familiarity with these tools, which you’ll use throughout this course and in future endeavors.
I, the Lab, hope you enjoy the process and have some fun along the way!
- In each lab session, you will follow this guide to get firsthand experience with the tools and techniques we have introduced to you in lectures and discussions. This experience will be essential to your Project work. You earn credit for participation by being engaged with the content of this lab and interacting with the staff when asked.
These labs are a low-stakes environment to get proficient with programming and software tools with support from fellow classmates and course staff. Please ask for help from course staff if you are stuck on something—we are here for you!
Lab 1 Learning Objectives
- Connect to
ieng6using SSH (Secure SHell) - Try out and understand some essential Unix/Linux commands
- Write a basic C program on
ieng6using Vim - Compile and run the C program you wrote
Icebreaker
-
Discuss the following with the people around you. Get to know your fellow group members!
-
How you’d like people to refer to you (pronounce your name/nickname, pronouns like he/her/they, etc)
-
Your major
-
One of:
- A UCSD student organization you’re a member of or interested in
- Your favorite place you’ve found on campus so far
- A useful campus shortcut or trick you know
-
What is your favorite movie, or (if you prefer) the last movie you saw? What genre is it?
-
Who is your favorite character and why?
-
What is your favorite thing about the movie?
Throughout this lab, we strongly encourage you to help each other. The staff is always there to help, but do try working together and helping each other out first.
During the labs, you will see these purple boxes, these are to help you know when there is an exercise to complete. If it needs to be checked off it will be indicated with a green box instructing you to get checked off. Please fill out your whiteboard as follows:
Github Setup
Make a Github account WITH YOUR UCSD EMAIL and fill out this form. https://forms.gle/pVQP1Xpc8akjqmTh9 If you already have a Github account, follow this link to add your UCSD email to your account. If you find yourself spending more than 5 minutes on this part, ask a staff member for help
Let’s connect to ieng6
First, open up a terminal window by following the instructions for your operating system.
- Windows: Do you have (Windows Subsystem for Linux) installed? (if you aren’t sure, assume you do not)
- No WSL: Press the Windows button, type in “Terminal”, then select “Terminal” or “Command Prompt” (if “Terminal” doesn’t exist).
- Once the window launches, type
sshand press Enter. If you see a red error message stating thatsshis not recognized, please follow the instructions here to enable SSH. - We do recommend installing wsl as it is a very useful tool! Let us know if you run into any issues on EdStem, in tutor hours, or in office hours.
- Once the window launches, type
- Yes, WSL is installed: Press the Windows button, type in “wsl”, then select “WSL”
- No WSL: Press the Windows button, type in “Terminal”, then select “Terminal” or “Command Prompt” (if “Terminal” doesn’t exist).
- MacOS: Click the Launchpad icon in the Dock, type in “Terminal”, then select the Terminal application.
- Linux: Press Ctrl+Alt+T to launch a terminal window.
As a student, you are assigned an account on the ieng6 server hosted by UCSD. These are similar to accounts you might get on other systems at other institutions (or a future job). We’ll see how to use your machine to connect to a remote computer over the Internet to do work there.
Your account name is the same account name as the one that’s used for your school Google account, i.e. it is the string that precedes “@ucsd.edu” in your school email address. In case you need to check the status of your student account, refer to the UCSD Student Account Lookup page.
Let’s use SSH (Secure SHell) to connect to ieng6 . Your command will look like this, but with the aname replaced by your account name. Don’t copy the $!
$ ssh Your account name@ieng6.ucsd.edu
The $ symbol is the prompt. In the terminal, it represents that you can type commands after this symbol to execute them. It is conventional to include $ when giving examples of commands to make it clear that they are user-written commands, as opposed to output from a command.
Since this is likely the first time you’ve connected to this server, you will probably get a message like this:
$ ssh aname@ieng6.ucsd.edu
The authenticity of host 'ieng6.ucsd.edu (128.54.70.236)' can't be established.
ED25519 key fingerprint is SHA256:8vAtB6KpnYXm5dYczS0M9sotRVhvD55GYz8EjN1DYgs.
This host key is known by the following other names/addresses:
    C:\Users\etomson/.ssh/known_hosts:1: ieng6.ucsd.edu
Are you sure you want to continue connecting (yes/no/[fingerprint])?
answer with: yes and it should say:
Warning: Permanently added 'ieng6.ucsd.edu' (ED25519) to the list of known hosts.
After this, you get a prompt to enter your password. This is the same password you use to log into your student account on other websites, like Canvas and Tritonlink. The terminal itself does not show what you type when you enter your password. This is conventionally done for your own security, so that others looking at your screen don’t see it. Just trust that it gets inputted when you type. Press Enter when you are done.
If the login process succeeds, you should see something like:
Last login: Tue Jan  7 10:00:00 2025 from 66.11.22.33
Hello aname, you are currently logged into ieng6-999.ucsd.edu

You are using 0% CPU on this system

To see all available software packages, type "prep -l" at the command prompt, or "prep -h" for more options.
[aname@ieng6-999]:~:45$
Now your terminal is connected to a computer that is physically somewhere else on campus, and any commands you run will run on that computer! We call your computer the client and the computer that is elsewhere the server based on how you are connected.
If, in this process, you run into errors and can’t figure out how to proceed, ask! Remember – it is rare for a tutorial to work perfectly. We often have to stop, think, guess, Google search, ask someone, etc. in order to get things to work the way the tutorial says.
To exit out of the ieng6 server and return to running commands on your local device, type exit as a command, or press Ctrl+D (which sends an EOF character). Please exit the ieng6 server now for the next section.
The Terminal and You
In your day-to-day life as a CSE 29 student (and as a software engineer), you’ll be making heavy use of the terminal. Best to get familiar with it early on.
A terminal is a text-based interface for a user to interact with the computer. There are various commands that a user can type into the terminal that perform different functions. Let’s take a look at some of them.
pwd - “Where am I?”
The location in the file system in which you are currently is called the “working directory”. You can use the pwd command to print the name of the working directory.
$ pwd
/home/linux/ieng6/oce/6k/aname
uname - “Who am I?”
Unix name will give you nformation about the unix or linux system you are currently on.
$ uname
Linux
This alone does not tell us much but there are several flags that are useful.
-a:print all information, except omit -p and -i if unknown-s: print the kernel name (this is the same as defaultuname)-n: print the network node hostname i.e. the name of the computer.
systeminfo - Who am I on windows?
As uname stands for unix name, it does not tend to work on Windows machines. Thankfully, windows has provided it’s own command to print information about the system – systeminfo.
$ systeminfo

Host Name:                     ELENA-M15
OS Name:                       Microsoft Windows 11 Pro
OS Version:                    10.0.26200 N/A Build 26200
(...)
It gives far more information than you would need for this lab, but do note that it includes the name of the computer equivalent to uname -n.
ls - Looking around
You can’t do much without knowing what exists in the current working directory to interact with. You can use the ls command to list out the contents of the current working directory.
$ ls
folder hello.txt
Most commands will have multiple pre-defined options which allow you to modify the behavior of a command. Options are usually written as a dash (-) followed by a few letters. Some common options for the ls command include:
-a: list all files, including hidden files-l: list in a long format, which shows additional information, such as permissions and time of creation-al: enables both the-aand-loptions for the same command--color: colors the output which onieng6makes all your directories blue and executable files green
If you would like to always have the colored output, run the following command which will add the line “alias ls="ls –color" to the end of a file called .bash_profile. You do not need to fully understand this yet.echo alias ls=\"ls --color\" >> ~/.bash_profile
If you get a message resembling: -bash: (...) .bash_profile Permission denied
Run: chmod +w ~/.bash_profile to give yourself permission to write to the file.
cd - Going Places
You can change your working directory to a different directory using the cd command with the destination directory as an argument.
$ cd folder
$ pwd
/home/aname/folder
There are also built-in symbols which refer to locations in the filesystem that you can use as arguments to commands.
/(slash) represents the root directory, which is the top-most directory in a file system. It has to start somewhere!~(tilde) represents the home directory, which is usually a specific directory assigned to each user on a system..represents the current directory...represents the parent directory, i.e. the directory in which this directory is contained.
mv - Moving Things
You can move your files with mv.
We have a misspelt file in the wrong location.
$ ls -R
.:
cse29  hellowrold.c

./cse29:
$ mv hellowrold.c cse29/helloworld.c
$ ls -R
.:
cse29

./cse29:
helloworld.c
Moved the file hellowrold.c into the cse29 directory and fixed it’s name. You can rename files, change their location, or both at once as shown.
cp - Copying Things
You can copy files with cp.
$ ls
alloc_basic.c
$ cp alloc_basic.c mytest.c
$ ls
alloc_basic.c mytest.c
Works exactly the same as mv except doesn’t remove the original file.
Good for when you want to make a variation of a file or have a backup.
scp - Securely Copying Things
you can securely copy your files with scp.
Assume I start on my machine which is windows – not ieng6
$ ls
fruits.txt
$ scp .\fruits.txt etomson@ieng6.ucsd.edu:~/
fruits.txt                                100%   31     0.0KB/s   00:00
PS C:\Users\etomson> ssh etomson@ieng6.ucsd.edu
$ ls
Downloads    Music      pokemon.sh    cse29fa24
cse29su25    cse8a      ece148        MailArchive
fruits.txt   cse29      cse29sp24     cse29wi26
Documents   juotes.sh   quotes.sh
The file fruits.txt was copied into my home directory on ieng6.
A general format for copying to ieng6 is:
scp <file you wish to copy> <username>@ieng6.ucsd.edu:<path on ieng6 to put it>username is the same as you used for ssh.
touch - Creating Things
The touch command is used to change the last modified date of a file (hence, touching the file). A neat bonus feature of touch is that it will create a file with the given name if the file doesn’t already exist.
$ touch random.txt
$ ls
random.txt
A quick side note - by default, the output of a command is printed out to the screen. But we can redirect the output into files using the > character.
For example,
$ pwd > random.txt
takes the output from pwd and redirects it into a new file called random.txt (thus it does not print to the terminal).
cat - Looking at Things
You can use the cat command to display the contents of a file. This command is designed to be used to concatenate files, but it is also commonly used to print out things.
$ cat mylocation.txt
/home/aname/folder
mkdir - Creating Directories (Folders) to Hold Things
You can use the mkdir command to make a new directory with the given name as an argument.
$ mkdir nestedfolder
$ ls
nestedfolder
rm - Removing Things
When a file has outlived its usefulness, we may wish to remove them. This can be done with the rm command.
For example:
$ ls
random.txt
$ rm random.txt
$ ls
Because the random.txt file got removed, our working directory is now empty, so ls doesn’t print anything.
man - Getting Help
Recall the command line options introduced for ls, -a and -l.
What if we wanted to learn more about what they do? What if we wanted to learn what other options ls has? How about the functionality and options of other commands? If only there were a manual for this information…
Luckily for us, there is. You can use the man command to look up the functionality of a command. For example:
$ man ls
LS(1)                                               User Commands                                               LS(1)
NAME
        ls - list directory contents

SYNOPSIS
        ls [OPTION]... [FILE]...

DESCRIPTION
        List  information  about the FILEs (the current directory by default).
        Sort entries alphabetically if none of
        -cftuvSUX nor --sort is specified
...
    -a, --all   do not ignore entries starting with .
...
    -l    use a long listing format
...
To navigate the manual page, you can use the up and down arrow keys. To exit the manual, press q.
Try looking up some of the commands we’ve learned about so far in the manual. Who knows? You might learn something new.
Who are you? – Whiteboard Activity
Using the commands above, fill out the following whiteboard with your group! Each group member should put their answer for each box.
A set of example answers have been given
As a group, call over your tutor/TA to get checked off for your whiteboard.
Who are we anyways? – Whiteboard Activity
Now that you’ve established who you are using some commands you just learned, the course staff has come together to make an activity for you to explore more commands from above and learn something about them.
- On ieng6, create a directory called
cse29, this will be the directory that contains all your work for labs- Within
cse29, create a directory calledlab1- Within
lab1, Run:cp -r /home/linux/ieng6/CSE29_SP26_A00/public/people .
the . at the end is the path for your current directory. This will recursively copy the entire directory we’ve made called people into lab1 since that’s where you are.
Using commands from above, write down some information you find. Each person should contribute at least one thing they found to the whiteboard resulting in something like this
As a group, call over your tutor/TA to share it with them and get checked off.
Inside lab1, create two directories called Music and Books
In Music and Books, create a couple of files with the names of your favorite songs and books respectively, here’s an example:
 lab1
 |----Music
 |    |----Auld Lang Syne.mp3
 |    |----Canon in D.mp3
 |----Books
 |    |----OSTEP.txt
 |    |----Frankenstein.txt
 |    |----The Little Prince.txt
 |----people
      |--(...)
HINT: to pass in strings with spaces as arguments, surround them in quotes, for example:
$ touch "Auld Lang Syne.mp3"Navigate back to the lab1 directory, and use the
lscommand to print out the directories AND all their contents.HINT: there is an option that lets you do this, try using the
mancommand to find thelsoption that enables you to print the contents of a directory recursively
The Vim Text Editor
Back in my day, before we had IDEs, we had to write all our code in the terminal with Vim, and we liked it!
Up till now, you have most likely been programming in a graphical editor where you could click around with a mouse and highlight things by clicking and dragging.
But CSE 29 is cool. And using the mouse is decidedly uncool (in our view). So we are now going to learn a keyboard-based editor. Because you will spend the entire quarter inside the terminal (and you will love it), knowing how to use a text-based editor like what we are about to introduce is incredibly crucial.
After all, all the awesome hackers in movies are always typing, have you seen a single movie hacker clicking around with a mouse? Blurgh.
Our terminal-based editor is called vim. It’s an incredibly powerful editor once you learn how to use it properly. However, the learning curve is very steep, which is why the more you practice in these earlier weeks, the better. In this lab, you will use vim to write a small C program while learning a few essential vim features along the way.
to get acquainted with
vim, you can run$ vimtutorto open vimtutor which is a tutorial in and of itself. Please complete sections 1 and 2 of vimtutor. If you are a bit low on time, you can skip 2.3-2.5 and do them later. Don’t worry about memorizing everything as you go, you can always revisit it later and some of the same information is provided below for your reference throughout the last activity.
Vim is highly configurable—using its own scripting language (VimScript), we can customize its behavior in a wide variety of ways. We can even install a Vim package manager and add plugins that make it feel like VSCode! For now, let’s start with some sensible defaults, like 4 spaces for indentation, syntax highlighting enabled, and automatic “smart” indentation. If you haven’t configured Vim on ieng6 before, run the following command to download and install our configuration file:
$ curl https://cse29.site/week1/assets/vimrc.txt >> ~/.vimrc
Now, we are ready to begin. Inside the lab1 directory you created in the previous section, run the following command to edit a new file named contains.c:
$ vim contains.c
The Insert mode: “Just type”
When you enter vim, you start in the Normal mode. Press i to enter Insert mode, where anything you type gets inserted into the file. You should see -- INSERT -- show up at the bottom left (the status bar).
In this mode, you can:
- Use your arrow keys to move your cursor around the file
- Press Backspace/delete to delete the character at the cursor, much like conventional text editors
- Press Ctrl+Shift+V (Windows and Linux) or Command+V (macOS) to paste text from your operating system clipboard
- Press Esc to exit Insert mode and return to Normal mode
While we’re in Insert mode, let’s write a small C program that demonstrates a linear search algorithm. Complete the following skeleton in vim:
#include <stdio.h>

int contains(int item, int arr[], int size) {
   // Write your solution here!
   // Return 1 if "item" exists in "arr" (which has length "size"), otherwise 0
}

int main() {
   int arr[] = {2, 9, 2, 0, 2, 5};

   // Call "contains" with an item of your choice, "arr", and the length of "arr".
   // Replace "0" in the following line with your function call
   printf("Result: %d\n", 0);
   return 0;
}
The Normal mode
Press Esc to exit Insert mode. The -- INSERT -- indicator at the bottom left should disappear. You are now in Normal mode, where you can:
-
Press
h,j,k, andlto move your cursor inside the text editor^ k Hint: The h key is at the left and moves left. < h l > The l key is at the right and moves right. j The j key looks like a down arrow. vYou can still use your arrow keys instead if you’d like! Psssst, no shame in doing so—professor Soosairaj does this, too!
-
Press
:to enter Command mode -
Press
iorato enter Insert mode- Try out both to figure out the difference!
-
Copy/paste: press
ytwice to “yank” (copy) the current line into vim’s internal clipboard. Presspto paste it at the current cursor position. -
Delete: press
dtwice to delete the current line and put it into vim’s internal clipboard. Presspto paste the deleted line at the current cursor position.
The Command mode
When you enter Command mode by pressing : in Normal mode, your cursor moves to the bottom line of the terminal, where you can type out commands. For now, we will only use two command shorthands: w for writing your changes (like pressing Save in a graphical text editor), and q for quitting vim. You can type :w to save your changes to storage, :q to quit (add ! afterward to force quit without saving unsaved changes), or wq to save and quit. So, when you are done editing in vim, you would type :wq from Normal mode. Pretty convenient, right?
By the way, if you ever change your mind and want to abandon your command, press Esc in Command mode to return to Normal mode.
A quick side note - avoid running two instances of Vim on the same file at the same time as this can lead to swap file conflicts. You should not close your terminal window to exit Vim as this will leave the swapfile there.
- Using
yyandpin Normal mode, change your code to make several calls tocontainswith different values foritem, printing out the result each time.- Using
ddin Normal mode, remove the line withreturn 0;inside themainfunction. This line is actually not required for themainfunction.- Save your changes and exit vim.
- To verify that your changes are saved, display the contents of
contains.cwithout using vim.
Vim has many more commands and shortcuts. You can complete more of vimtutor on your own time for a guided tutorial through them.
Compiling and running your program
Now we want to be able to run our program. First we will compile it using gcc, and then we will run our executable file.
Compiling
GCC, our C compiler of choice, takes .c files and compiles them into our executable. for now we will only have 1 .c file and we will give it as our first argument to gcc, giving us:
$ gcc contains.c (Don’t run this yet!)
However, this would create an executable named a.out and we would like our file to be named contains. (Yes, executable files don’t have an extension in Unix/Linux.) We can use the -o flag to do this. -o takes the next argument and renames the output file to be that name:
$ gcc contains.c -o contains (Don’t run this yet!)
We would also like to see any warnings that the compiler catches even if it doesn’t prevent it from compiling as an error. We will use the -Wall flag, which stands for Warn all. (Run this!)
$ gcc contains.c -o contains -Wall
If you don’t see any output from this command, then it has succeeded. To run our program, since it is named “contains”, we shall type:
$ ./contains
You should see your linear search implementation in action.
Congratulations! In this lab, you have created, compiled, and executed a C program. If your program has not run, please ask a staff member near you for help.
If you find yourself wondering about the origin of the name ieng6, The following was provided by the Office of Engineering Computing:
“ieng6 is a load-balanced multiprocessor Linux server that is maintained by ITS. This hostname originated decades ago, and unfortunately, we do not know why it was named ieng6. It may not even stand for anything.”
While the history of the name remains a mystery (at least for the time being), we did learn something interesting about what it is. Many people can use ieng6 at the same time.
Being a “multiprocessor” system means each machine(201, 202, 203 …) has multiple CPUs (or cores), so it can run many tasks at the same time.
Being “load balanced” means that when people connect to ieng6, they are distributed across multiple machines behind the scenes so no single machine becomes overloaded with work. When you SSH into ieng6 you are placed on a specific machine (such as ieng6-201, ieng6-202 or ieng6-203) which you can see in your prompt. Which one are you on? Is it the same as the people around you?
“Linux” is the operating system it runs. Other operating systems you may be familiar with include Windows and macOS.
While that’s some great information, it didn’t answer our question regarding the name. Not to worry, Caleb Crawford of the IT Services department, knower of many things ieng6, has answered many questions.
“For some history, ieng stands for “Interactive Engineering” and dates back to when we had machines in AP&M that you had to use a video terminal to interact with the machines. The 6 in the name is from the IP Address originally assigned, which was 132.239.50.6. There used to be other “ieng” machines, you may encounter someone that remembers ieng9 that used to host Solaris SPARC used in CSE30 and CSE120.
ieng6 and almost all of the infrastructure students might use is physically located in SDSC. The ieng6 machines are entirely virtual machine based so they’re balanced on a cluster of hardware supporting most ITS.
ieng6.ucsd.edu is a round robin load balancer that currently balances number of connections between ieng6-201, 202, and 203 (this will be increasing this summer). 201-203 are SSH only machines, everything else also allows RDP desktop sessions which you can connect to from campus/VPN or via linuxcloud.ucsd.edu. All the ieng6 machines are open to use as needed but we may point courses at specific sets of machines depending on what’s needed for the course.
ieng6-240 - 253 are the original desktop cluster and the number is based off their IP address.
$ host ieng6-240
ieng6-240.ucsd.edu has address 128.54.70.240
ieng6-640 and ieng6-641 were originally the first x86_64 deployments and are currently used to support old software that needs CentOS 7.
ieng6-700 through 702 and ieng6-300 through 309 are higher resource machines (more memory + CPU) which were added as we needed to support more intensive desktop software/more desktop sessions total during covid.
ieng6-ece-01 through 20 are machines specifically for ECE courses.
There used to be igpu-### machines which were GPU compute servers that eventually turned into the DSMLP cluster.
For home directories, the old style “OCE” paths means your account was setup prior to May 2025 and didn’t get migrated to the new format. I don’t know the particular history on how that hash layout was developed but it was in use for 30+ years. Accounts used to need to be flagged as “Open Computing Environment” to get persistent storage and compute resources that you can use outside of a specific course, which mattered a lot more when disk and cpu resources were limited. Non OCE accounts used to look like “cs29sp26aa” and were allocated for specific courses and removed after the quarter.
New accounts are standardized with the home directory bin being the last 3 digits of your UID. Note your UID is 112263
$ getent passwd etomson
etomson:*:112263:20:Tomson, Elena:/home/linux/ieng6/students/263/etomson:/bin/bash“
Lab 2: Version Control with Git
Welcome to Lab 2, glad you’re here! For a later section of the lab, you will work in groups of 2-3. Before starting the lab, form your group and do the icebreaker activity together. Let a TA or tutor know if you don’t have a group!
Lab 2 Learning Objectives
- Enable your
ieng6account to communicate with GitHub on your account’s behalf - Familiarize yourself with the conceptual model of Git
- Try out essential operations in Git on the command line
- Use Git to undo a destructive change
Icebreaker
In your groups, please discuss the following:
- Pick a song as the soundtrack of your life! Why you did you choose this song?
- What’s your favorite genre? Who’s your favorite artist?
Please fill out this welcome survey
PA1: Start Early Start Often
This is the motto of the CSE department.
The Key to Git
Recall from last lab how to log into your ieng6 account:
$ ssh your account name@ieng6.ucsd.edu
Please log into ieng6. Within your ieng6 account, use the following command to generate a new key pair, replacing github_email with your GitHub email address:
$ ssh-keygen -t rsa -b 4096 -C github_email
You’ll be prompted to “Enter a file in which to save the key”. Press Enter to accept the default location.
You are about to generate a public key and a secret private key called ~/.ssh/id_rsa on your computer. If anyone gets ahold of that file they can SSH into all of the things you can SSH into, so you want to protect that file. One way you can protect it is to add a passphrase which is the next prompt it will give you. Press Enter twice to continue without setting a passphrase. Though if you really want to set a passphrase, refer to GitHub docs on passphrases.
Adding your SSH key to GitHub
By default, the public SSH key is saved to a file at ~/.ssh/id_rsa.pub.
Instead of typing out the whole filename, you can type out some prefix of the name (e.g. ~/.ssh/id), and press Tab to autocomplete the name.
In this case, tab complete won’t complete the full filename, since the private key happens to be named id_rsa.
Please be too lazy to type out entire filenames and use tab complete instead!
View the contents of ~/.ssh/id_rsa.pub (using cat), then copy the contents of the public key file to your clipboard.
On the GitHub website, click your profile picture in the top right to open a menu, and click on “Settings”.
On the left, open “SSH and GPG keys”, then click on “New SSH key”.
Populate the fields as follows:
- Title: “ieng6”
- The title doesn’t affect the functionality of the key, it’s just a note for you that this key is tied to your ieng6 account.
- Key type: “Authentication key”
- Key: Paste the contents of the public key file here (entire block including the email portion).
Click “Add SSH key”. You may need to confirm access to your account on GitHub at this point.
Testing your SSH key
Finally, test your connection to GitHub with the command:
$ ssh -T git@github.com
If this is your first time connecting to GitHub, you might get a warning about the “authenticity of host can’t be established”. This is a warning for you to make sure that you’re connecting to the right thing. For the purposes of this lab, we assume that GitHub didn’t suddenly get hacked, so you can safely respond with “yes”. But if you’re really paranoid, you can check GitHub’s public key fingerprint here.
After a successful connection, it should output Hi <your-username>! You've successfully authenticated, but GitHub does not provide shell access.
If you did not get this success message, please ask someone for help, you will not be able to complete the next part if your ssh keys are not properly set up.
That should conclude the GitHub SSH key setup process. If the others in your group are struggling with this, please help them! The next step will require everyone in your group to be able to successfully connect to GitHub.
Git Gud Bro
For this section of the lab, you should work in groups of 2-3. Let a TA or tutor know if you don’t have a group!
Before you start using git hands-on, we should establish some vocabulary and concepts about git and GitHub.
- git is a command line program that enables version control, i.e. the ability to track and switch between different versions of your code, including switching to past versions.
- A repository (or repo) is a folder, usually containing code, which is configured to work with git to manage different versions. When you forked the repository on GitHub, it created a copy of the original repo for you that you can edit.
- GitHub is a website which hosts repos, allowing you to save your work on a server, and can allow people to contribute to others’ repos.
If there is any software which most (if not all) programmers use, it’s git and its integration with GitHub. That’s why knowing how to use git and having a GitHub account are essential for programmers.
git organizes your code files in a particular way to give you flexibility in how you manage different versions of your repo, which we’ll visualize below. Note that git does not actually create distinct “areas” in your repo directory and move files between them, but we may refer to them analogously as if they were physical areas that files move in and out of.
We refer to files stored on your device as local, and files stored on GitHub (in a server far away) as remote. Technically, files in your ieng6 account are remote relative to your machine, but we will consider them local relative to the GitHub servers.
-
The working directory refers to all of the files and folders in a specific version of your repo. Note that this definition only applies to git repositories. Don’t get it confused with your current directory in the terminal (
pwd)! -
The local repo contains a history of committed files (or just commits). You can think of a commit as a set of modified files which are “packaged” together and labeled. This method lets us easily group and track the history of changes for our files.
-
The staging area temporarily contains files that will go into the next commit. This exists to let you neatly organize what should be committed. For example, if your workflow involves making changes to lots of files, but you want to separate them into different commits, you can separately stage and commit groups of changes.
-
The remote repo is a repo that is hosted on GitHub. After commits are made to the local repo, you can push them to the remote repo to save your work on a server.
git contains many commands which let you manipulate and move files within this system of organization. We’ll practice some essential commands in the upcoming exercises.
If you did not complete Lab 1, you may run the following commands to download our shell script to create a cse29 folder with the directory tree example contents:
$ wget https://cse29.site/week2/assets/lab1_commandline/exercise.sh
$ chmod 755 exercise.sh
$ ./exercise.sh
Aside: The executable bit
The file permissions scheme used in Unix-style
systems is designed to protect files from unauthorized access and
unsafe execution. It prevents you from snooping into other users’ files on ieng6.
It also prevents you from executing a file by accident. Under this scheme,
three bits describe the operations that can be performed on every file:
Read (r), Write (w), and Execute (x). To see the settings for
these bits for all the files in a directory, run ls -l and focus on the
second, third, and fourth character in each row, which
specify what the owner of the file is allowed to do. For example, in
-rwxr-x---, rwx means the owner can read, write, and execute the file,
whereas in -r--r-----, r-- means the owner can read but cannot write to or
execute the file.
Why does this matter for shell scripting? Well, when you create a script file,
it starts out with the Execute bit disabled, which means you can’t execute the
file by default. (If you try, you would see Permission denied.) To be able to
execute your script, you need to set the Execute bit by running
chmod +x
file(s) to mark executable
. If you’d like, you can verify the outcome of this command
using ls -l. Here’s what our textbook
has to say about the chmod command and file permissions in Unix.
Several students in the past had the misconception that you need to run chmod +x every time you run the same script. Since a file’s permissions are stored
alongside it, permission changes are stored permanently, and script files don’t
unset their executable bit every time they run. So just set it once for each
script!
Fork the Repo
A fork of a repository is a personal copy of the repository that you can make changes to without affecting the original repository. To fork a repository, click the “Fork” button in the top right corner of the repository page.
Have ONE person in your group fork the Lab 2 starter repository here.
Share the Repo
In order for the rest of the team to have the correct access rights to the repository, it must be properly shared in Github. To add the rest of your teammates, click “Settings”
Then click “Collaborators”
Now you can add your teammates using the “Add People” button and using their Github Usernames
Clone the Repo
First, find the SSH url for your group’s repo. You can do this by following the guide above, clicking the buttons in the order presented to copy your repo’s URL onto your clipboard. Making sure you get the SSH url and not the HTTPS url!
To get a copy of the remote repository you just created onto your local machine, use the git clone command to clone a copy of the repo like so:
$ git clone ssh_url
Each group member should clone their repo into their cse29 folder, created from the previous lab.
A new folder will be created in cse29 with the remote repo name and set up as a local repo. Change into this repo directory.
Make sure you changed into the repo directory!
If you accidentally cloned the repo into the wrong place, you can move the repo directory to the right place with
$ mv repo_name ~/cse29/repo_name
, where repo_name is the name of your repo. This command is also used to move and rename files.
Each member of your group should have now successfully cloned the lab2 repo onto ieng6 in the cse29 folder. Make sure you have all correctly completed the command line exercise from lab 1, with the Books and Music directories being correctly named and structured.
“You have good taste!”
Remember those books and songs that you created last week? Now it’s time to pool them all together into one
Copy over the content of your lab1 directory into your lab2 repo. You can do this by using the cp command like so:
$ cp -r ../lab1/* .
This command “recursively” (-r) copies “everything” (*) from the lab1 directory in the “parent directory” (..) into the “current directory” (.).
You can use git status to see the state of the local repo with a new file. git status is a generally useful command to use to look at the state of the repo at any time; expect to be using this often! Its output will look something like this:
$ git status
On branch main
Your branch is up to date with 'origin/main'.

Untracked files:
  (use "git add <file>..." to include in what will be committed)
        Books/
        Music/
        contains.c

nothing added to commit but untracked files present (use "git add" to track)
“Untracked” is a status for files and directories that have not been committed to the local repo previously, indicating that git is not tracking the history of changes in this file. After a file becomes tracked, and further changes are made to the file, the file is referred to as “modified”. git add is used to both track untracked files and stage modified files:
$ git add Books Music
Here, we are ignoring contains.c because letting Git track it would lead to thorny merge conflicts with your group later on, as each of you has slightly different code in it. Check using git status to see that Books and Music are now staged.
Next, use $ git commit -m “insert-commit-message”
to commit all files into the staging area to the local repo. Replace insert-commit-message with a brief description of what changed in this commit.
The -m option allows the user to directly write a commit message as a string in the command. If you were to run git commit without this option, it will open vim and instruct you to write a commit message there. Generally, commit messages are concise enough that using a text editor to write them out is unnecessary.
Writing a meaningful commit message is quite useful, and usually expected in a professional setting. The commit message serves as a way for others (and yourself, in the future, looking back) to easily understand what changes were made in a commit without having to read through the changes manually.
Besides -m, there are other common options that programmers use with git commit:
git commit -a: automatically stages all modified files in the working directory, but not any untracked files.git commit -am: has the behavior of both-aand-moptions.
At this point, all your teammates should have their Books and Music directory committed in their local repository. You should now work together at this point.
Have one teammate (let’s call them “Person 1”) push their changes from the local repo to the remote repo:
$ git push
Next, have another person (let’s call them “Person 2”) try running git push. You should run into an error that starts with the following:
! [rejected]        main -> main (fetch first)
error: failed to push some refs to 'github.com:CSE29Spring2025Students/lab2-<your-team-name>.git
This is git’s way of reporting a conflict between the remote repo (which has person 1’s commit) and the local repo (which has person 2’s commit). A conflict exists because the two commit histories “diverge”, taking on different paths. Do as the message tells, and use git pull to pull your teammate’s changes:
$ git pull
You might see the following hint as a result:
Hint: You have divergent branches and need to specify how to reconcile them.
Hint: You can do so by running one of the following commands sometime before
Hint: your next pull:
Hint:
Hint: git config pull.rebase false # merge
Hint: git config pull.rebase true # rebase
Hint: git config pull.ff only # fast-forward only
Run the first suggested command (git config pull.rebase false) to select merge as the default way to reconcile divergent branches. You can learn more about the difference between rebasing and merging here, which claims that the golden rule of rebasing is to never use it on public branches. After this command, retry git pull again, which should merge Person 1’s contributions with the local repo.
Now you can safely push your changes:
$ git push
This pull and push cycle is your bread and butter in collaborative development in git, where you pull your teammates’ changes, and push your own changes on top of them.
Sometimes, if the changes you make on your local repo are incompatible with the changes a teammate made, a merge conflict will occur when you attempt to pull your teammate’s code. All kinds of headaches result from this, but luckily, you don’t have to worry about that. For now.
Have the rest of the teammates pull the changes from remote, and push their changes.
To see who pushed what, you can use the git log command to log all the changes that were made by both you and your teammates. Try it! (To exit out of a long git log, press q)
$ git log
To see specifically who added what, you can add the --name-status option to the git log command.
$ git log --name-status
Now you can see what songs and books your teammates enjoy! Albeit it probably would have been easier to just have a conversation and talk about your preferences, but alas, this is the CS major way of doing things.
We’ll revisit Git in a later lab and in your own time, if you’d like to learn more about some of the concepts introduced today such as commits and how they are tracked, you can look into the Le Git Graph browser extension and its GitHub repository. You can also check out this interview with the creator of Git that celebrates its 20th birthday this year, woo!
Verify each team member has a repo with you and your teammates’ shared Music and Books folders. Run git log --name-status to verify who wrote each change. Call over a staff member once everyone is here to get checked off.
Git people
Recall the people directory from lab1? If not, no need to worry but once you git clone to explore the people, our descriptions of ls and man may be of use to you.
Now you get to add data of your own!
Write each git command that you use in the following activity on your whiteboard along with a short description of what it did on your whiteboards. (Please let each person write at least one).
After re-copying the people directory to get any new additions cp -r /home/linux/ieng6/CSE29_SP26_A00/public/people .:
Make a Students directory alongside the Instructors, TAs and Tutors directories in your workspace.
Create a directory in Students that is your name
Make and populate a data.md file with and fun facts you want to share (we have an outline.md file you can use or you can make one of your own)git push each team member’s changes to github so you can see them all there.
From github, you can then look at files by clicking the people folder from this screen
From here you can go look at the .md files which use markdown formatting which add formatting to our plain text files. Go find one of your staff members’ data.md to see some formatting options in practice.
Oops! Undoing destructive changes
To illustrate that Git is useful even for individual projects (like your PAs), let’s create a scenario where you make a destructive change to your code. We’ll reuse the contains.c file you may have written in Lab 1.
If you wrote contains.c and successfully compiled it in Lab 1, check if you have contains.c in your local repo directory. If you don’t, use the cp command to copy it into the root of your Git repository. You may find the following command helpful—it means “Copy the contains.c file from the lab1 directory found inside the parent directory into the current directory”. You may need to navigate to the root of your Git repository before you run it.
$ cp ../lab1/contains.c .
..means “parent directory”.means “current directory”, as in the output ofpwd(remember?)
If you did not successfully compile contains.c in Lab 1, you may run the following command at the root of your Git repository to download a working version from us.
$ wget https://cse29.site/week2/assets/lab1_commandline/contains.c
Occasionally, ieng6 throttles connections to GitHub. If this command gets stuck for too long (like 5 seconds), abort it by pressing Ctrl+C and try it again. No need to copy-paste: just press the up arrow in the terminal to populate it with a previous command. You’ll find the arrow keys very helpful in the terminal!
Now, let’s package our change (of adding a C source file) by making a commit. Use what you have learned in the previous section to (1) let Git track contains.c and (2) make a commit that represents adding contains.c to the repository. Do not push your commit onto GitHub! Feel free to verify your work with git log and git status.
We’re ready for the destructive change. Read the following commands to understand what they do, confirm your understanding with your group, and run them:
$ gcc contains.c -o contains -Wall
$ ./contains > contains.c
$ cat contains.c
Oh no—your source code is gone! If you run git status now, you should see the following:
Changes not staged for commit:
 (use "git add <file>..." to update what will be committed)
 (use "git restore <file>..." to discard changes in working directory)
       modified:   contains.c
To undo our destructive change, we precisely need to “discard changes in working directory” relative to our last commit. So, let’s follow the instructions from git status to restore contains.c. Please compose the command on your own from the instructions.
Make sure everyone in your group was able to successfully restore the once destroyed contains.c contents.
You might have heard about git revert, git reset, and git restore. Each command performs a unique operation. Learn more about what they do with Git’s official documentation.
A Bit of Practice
One of the important skills of PA1 that you will need to know is bit manipulation. That’s what we’re going to practice today!
In bitstrings.c, you’ll find a series of bitstrings along with incomplete assert statements. Your job will be to fill each instance of _ with the correct bitwise operator to make the assert pass.
For your reference, here is a code snippet with usages of common bitwise operators you may find useful, taken from GeeksForGeeks:
// a = 5(00000101), b = 9(00001001)
unsigned char a = 5, b = 9;

// The result is 00000001 (AND)
printf("a = %d, b = %d\n", a, b);
printf("a&b = %d\n", a & b);

// The result is 00001101 (OR)
printf("a|b = %d\n", a | b);

// The result is 00001100 (XOR)
printf("a^b = %d\n", a ^ b);

// The result is 11111010 (NOT)
printf("~a = %d\n", a = ~a);

// The result is 00010010 (left shift)
printf("b<<1 = %d\n", b << 1);

// The result is 00000100 (right shift)
printf("b>>1 = %d\n", b >> 1);
This is the submittable checkoff for the lab. Submit the repository to Gradescope as a group (1 person submits and adds the rest of the team).
Next steps
If you finish with the lab content above you may any do the following:
- Continue reading and get a sneak-peak on topics covered in lab 3! 👀
- Do the parts of the lab marked as “On your own time”
- Work on PA1
Lab 3 Preview: Debugging with gdb
If you haven’t already, at some point in this class while writing your programs you will surely encounter a segmentation fault (or just segfault for short). These occur when you try accessing memory that you’re not supposed to, and are your computer’s way of saving you from harming it.
Intro to gdb commands:
- To use gdb, make sure you’ve compiled your program with “debug symbols” like so:
$ gcc -g YOUR_CODE.c
- Run your compiled code in gdb
$ gdb YOUR_BINARY
- This puts you into a gdb prompt: normal terminal commands don’t work here, and you can instead run gdb-specific commands
(gdb) run # starts running your program
- If your program stops running or segfaults in gdb, print out the backtrace (also called a “stack trace”)
(gdb) backtrace
or
(gdb) bt
If you would like to see this in practice you can try it on any of the 3 buggy files in this repo.
Use the following commands to print out values at the point the program stopped:
(gdb) info locals(gdb) info args(gdb) print VALUE (or p VALUE)- You can print any variable or expression, e.g.
print x,p arr[5],p ((x & 0b1111) << 3)
- You can also specify a format to print in
print/t(binary),print/x(hex),print/d(decimal)
- You can print any variable or expression, e.g.
(gdb) x ADDRESS- This prints out memory at an address, e.g. strings / arrays / pointers
(gdb) x/16cb str1- This prints the first 16 bytes of
str1as characters
- This prints the first 16 bytes of
(gdb) x/20xb str2- This prints 20 bytes of
str2in hex
- This prints 20 bytes of
(gdb) x/4dw arr- This prints 4 “words” (i.e. int32s) of
arr, as decimal numbers
- This prints 4 “words” (i.e. int32s) of
- You can use the following reference card for reference on gdb commands, and format commands for x and print.
Lab 3: Debugging with GDB
In this lab, you will get hands-on experience using GDB to debug C programs. GDB will become an essential tool for your Project work as this course develops, so lock in!
Lab 3 learning objectives
- Recognize the need for debugging using a debugger
- Compile a C program for debugging
- Catch possible bugs using a compiler
- Run a program in GDB while stopping at breakpoints
- Use various GDB commands to observe and control program execution
- Use GDB to troubleshoot a crashing program
Whiteboard activity #1
Icebreaker
The CSE 29 genie, which runs on ieng6, would like to grant you 3 wishes. You may wish for anything you want, except you may not wish recursively (i.e., wish for more wishes). What do you wish for?
Warm-up
Please write each other’s icebreaker answers on your whiteboard as well.
Color ls
- if you did not opt to make your
lscolorful in week1, now is the time. - Run
echo alias ls=\"ls --color\" >> ~/.bash_profile- if you have file permission issues, you can use
chmod u+rwx ~/.bash_profile
- if you have file permission issues, you can use
- you can use
source ~/.bash_profileto apply these changes right now.
Part 1: -W(arn)all
Our compiler gcc is designed to catch possible errors at compile time and warn you. While it gives you some of these warnings by default, we can force it to display all possible errors it detects by telling it to W(arn) all using -Wall flag. We can add this flag as follows:gcc myprogram.c -o myprogram -Wall
The order of flags given to gcc does not matter. The only case where it does matter is if a flag takes an argument(s). For example, -o is followed immediately by what the binary file will be named.
- Clone this repository
- Navigate to the
Walldirectory and fix the programs. All bugs will be reported by compiliing using the-Wallflag
Part 2: What and why debugging?
Debugging is the practice of finding and fixing errors in programs. There are no real bugs in your program, although this has actually happened at least once before.
Like programming, debugging is also an incremental process. Programmers often need to isolate and debug one error at a time, rather than all errors at once.
We could insert some print statements into our code to try and figure out what’s going on—for small programs, print statements are often enough! However, there are several situations where we would want to use a debugger instead:
- If your program reports a segmentation fault, it can be difficult to pin down exactly where the segfault took place using print statements. A debugger can pause your program when it crashes and enable you to inspect its final state.
- If you are searching for a bug in a loop with many iterations, searching through print statement output from that loop can be quite cumbersome.
- You might work on a program for which you can’t see the output of print statements (like your web browser or vim itself). In this case, the debugger is a convenient tool for inspecting program state.
GDB (GNU Project Debugger) is a command line program that offers a convenient way for us to pause execution at any point in the code, manually inspect the values of any variable in the scope, and walk through the program step-by-step.
Debugging Activity
The gdb directory contains several programs which we will debug with GDB: index_of_E and charshift.c. We’ll start with the index_of_E program to introduce basic GDB commands, then look at charshift.c to talk about segmentation faults and how to debug them with GDB.
The correct behavior of index_of_E is to find the index of the first occurrence of the character E in a string str.
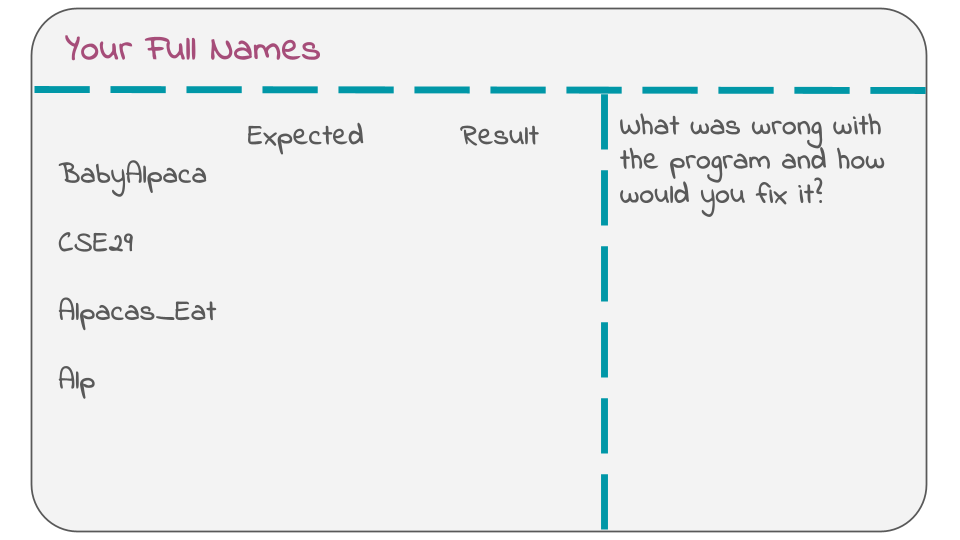
Predict the output for the following strings, “Baby_Alpaca”, “CSE29”, “Alp” and “Alpacas_Eat”. Fill out your whiteboard, leaving some extra space for your later bug fix like so:
Compiling for GDB
In order to use GDB, we have to compile our program with the -g flag. This tells the compiler to add some extra information to your executable file, which GDB will use. index_of_E was compiled using the following command.
$ gcc -o index_of_E -g index_of_E.c
Running in GDB
To run the program in GDB, use the gdb and pass the program as an argument:
$ gdb ./index_of_E
This will spit out several lines of text, with some software and legal information that we don’t need to worry about. In the last line, you should notice that the terminal command prompt $ (as well as the other stuff before $) has been replaced by the GDB command prompt (gdb). This means that the GDB program is active and ready to receive commands.
Use the run command to run the program in GDB. Since this program takes in a command line argument, you can provide it like so:
(gdb) run CSE29_is_fantastic!
This is just like running the command ./index_of_E CSE29_is_fantastic!. For now, it runs through the program without stopping. GDB might say something here about “Missing separate debuginfos”, but don’t worry about this. GDB is just asking to install some extra packages to get more information for debugging, but these aren’t necessary for our purposes right now.
To quit out of GDB, you can use the quit command.
(gdb) quit
In the future, please add -Wall to your compilation command to ask the compiler to help you find potential bugs.
Breakpoints
To pause execution at some point in the program, we have to set a breakpoint. Restart gdb ./index_of_E. Use the break command and give it a location in the source code that you want to pause execution at. At the moment, we’re not too sure exactly which part of the code is wrong, so we’ll pause at the beginning (the main function) and go step-by-step from there. You can use either
(gdb) break main
to automatically set a breakpoint wherever the main function is. which happens to be line 12 in index_of_E.c, or if you had the source code and knew the line number:
(gdb) break index_of_E.c:12
to set a breakpoint at line 12 in the file index_of_E.c, You can set breakpoints at any line in a source file, but usually we find it helpful to set them at the start of functions, to investigate the behavior of a function from its beginning.
You can use the info breakpoints command to list out which breakpoints have been set, as well as some information about where they are and what their associated number is. You can delete breakpoints with the command delete <number> where <number> is the number associated with the breakpoint.
After setting a breakpoint, you can run the program again (copy the run command from earlier) and see that it pauses execution right where the breakpoint is.
Part 3: TUI, Commands, Segfault, and BackTrace
TUI in GDB
Notice that GDB printed out a single line of code from the source file. This is the line of code that is about to be executed next. Here, you can use the list command to print out some of the surrounding code. This can be helpful to contextualize where the code is running.
The layout src command may also be helpful to enable a TUI (Text User Interface) for GDB that automatically renders a portion of the source code in the top half of the screen. The highlighted line in the TUI shows which line of code is to be executed next. To disable the TUI, use tui disable. Alternatively, press Ctrl + X, followed by A.
(gdb) layout src
The TUI won’t render any source code unless there is a program that is active, i.e. in the middle of execution.
Sometimes the TUI can get messed up if the program prints something out (which index_of_E does). When this happens, try using the refresh command to refresh the TUI and hope that it will restore its correct format. If something seems really messed up, try disabling and re-enabling the TUI.
On the left hand side of the TUI, you can see that the breakpoint is marked with B+>.
Basic GDB commands
After setting a breakpoint and running, execution is paused right after we enter the main function, before any other code is executed. You can verify this by using the print command to print out the contents of the variable result:
(gdb) print result
and see that it contains an uninitialized value. We see this because the line that initializes the variable has not been executed yet.
To run the next line of code, we use the next command:
(gdb) next
The highlighted line has moved on, indicating that the previous line has been executed. You can check the values of argc and argv using the print command, which accepts any valid expression in C:
(gdb) print argc
(gdb) print argv
(gdb) print argv[0]
(gdb) print argc < 2
Let the program finish by using the continue command. Does its output match what you expect?
We now know that this input exposes a bug inside index_of_E, so we want to look into this function with GDB. Let’s restart the execution and make line-by-line steps. Run the break main command to have the program stop when the main function begins, and then use the run command to start the program again.
Use next to execute the program up until, but not actually executing, the call to index_of(). You’ll know that index_of() is next to be executed, but not executed yet, when the line of code is highlighted. This time, instead of using next to run the entire index_of() function at once, use the step command to step into the function and begin executing line-by-line from inside:
(gdb) step
GDB also provides shortcuts for some commonly used commands, which can be used in place of the full command name. Some of those include: r for run, q for quit, b for break, p for print, n for next, and s for step.
In addition to shortcuts, inputting no command and pressing Enter will automatically execute the most recently used command. This can be helpful when you need to use next repeatedly.
Tip: If your terminal looks a bit messed up, try pressing Ctrl+L, which will refresh the window.
Then continue using next to run through the loop and figure out why index_of() is buggy. Try printing out the relevant variables as you go through each iteration. Once you figure out why index_of() isn’t working, write what the problem was along with how you would fix it on your whiteboard.
Write the fix for index_of_E on your whiteboard and ask a staff member to check it off.
This buggy program demonstrated an example of a logical error. A logical error is one in which the behavior of the program is different than what we expect it to be, without refusing to compile or crashing at runtime. However, before your fix, it was theoretically possible for this program to crash—why do you think it was? Feel free to verify your thoughts with your peers, tutors or TA.
When you tried to print str inside index_of_E, GDB printed the entire string, just as we expected. However, what if you want to print the contents of an integer array passed into a function?
If you’d like, try this with contains.c from our previous labs (you can wget our version if you don’t have one—visit Lab 2’s instructions for the command). When you try printing out arr like you did while in main(), you’ll realize that it prints out some hexadecimal number, instead of its contents. This happens because arr is passed into contains() as a pointer to the start of the array. The hexadecimal number you see is the address of the start of the array. You can use print *arr (arr with the dereference operator *) to dereference the pointer and get the value at the start of the array, or print *arr@NUM to print out the values stored at address arr and the next NUM addresses. This means you can use print *arr@6 to print out all of the contents of the size 6 array.
Segfault and Backtrace
Use the following guide to find and fix the following bug in charshift.c.
If you break or lose a file. Recall:
Git Restore
Another common type of error is a segmentation fault (or just segfault). Segmentation faults can happen when we try to access someplace in memory illegally (yes, that’s the technical term). In charshift.c, we’ll look at an example of that.
Compile charshift.c for GDB and try running ./charshift. It should immediately crash and give you a Segmentation fault (core dumped) error, telling you that some kind of illegal memory access happened. Most unhelpfully, the error message does not care to tell you why or even where it happened. Somewhat helpfully, GDB can at least answer the “where”. From this lab onward, whenever you see your program segfaulting, you should consider debugging it with GDB.
Start GDB with the charshift program. This time, instead of setting a breakpoint, we can let the program run through and give us a segmentation fault. GDB immediately tells us where the segfault happened and gives us a line number. From the output, we can see that the segfault occurred in shift_chars(), where we attempt to dereference the pointer and see if it is in the range of capital letters. But main() calls shift_chars(), so which one is the one causing the error?
Here, we can use the backtrace command (or the shorter bt) to show a backtrace (also called a stack trace) of the functions that were called leading up to the segfault. The output shows that the segfault happened in shift_chars(), when shift_chars() was called from main() at a certain line. This helps you discern which specific call to a function causes a segfault, when you have multiple calls to the same function. Feel free to run layout src to help you find the line referenced from the backtrace.
Since we know that segfaults are caused by illegal memory access, and we know that line 6 in charshift.c caused a segfault, we can infer that ch probably contains an address that the program can’t access legally. Confirm this by running print ch. Then, run print str to see the address of the beginning of the message. What do you notice between these two addresses, and what does that imply about the loop in shift_chars? This should help you pinpoint and fix the bug. Feel free to work with your peers and ask your tutors/TAs for a hint if you’re stuck!
Debugging practice
There are 3 buggy programs in the gdb directory with names buggy*.c.
Use what you have learned in this lab to fix these programs, then submit them to gradescope by Monday, October 19th at 11am.
Identify yourself to ieng6
With this setup, each time you log in to your ieng6 account, you have to type the password. This can get a bit tedious. Luckily, there is a cool and interesting way to avoid this while still staying secure using SSH keys. You should perform the following on the device your frequently ssh into ieng6 from, not particularly on a lab computer.
- Verify that you are not logged into
ieng6. If your prompt does not contain the stringieng6, then you’re probably not on it. - Run
ssh-keygen -t rsa -b 4096. This command will generate a pair of SSH keys for you: one public (ends in .pub) and one private. If the program claims that the keys already exist, answer theOverwrite (y/n)?prompt withnto prevent overwriting your existing keys. Otherwise, keep pressing<Enter>until the program shows some text it calls the “randomart image”. - Expand the instructions that match your system below:
If your prompt ends with $ or % or #, not > (macOS, WSL, Linux) (Click to show instructions)
Runssh-copy-id username@ieng6.ucsd.edu, and enter your password (one last time). The program should claim that it has installed your key.
If your prompt ends with > (Windows) (Click to show instructions)
- Log into ieng6 with
ssh(using your password as usual) - Run
mkdir -p .sshin the terminal - Log out of your remote account by pressing Ctrl+D or typing
exit. - On your local machine, run the following command:
type $env:USERPROFILE\.ssh\id_rsa.pub | ssh username@ieng6.ucsd.edu "cat >> .ssh/authorized_keys"
(Credit to Christopher Hart for this convenient command. Please note if the above command does not work, copy in your full path to the SSH key)
Try to log onto your remote account again. You shouldn’t be prompted for a password anymore. If you are, ask for help and carefully review the steps above with your group.
Next steps
If you finish with the lab content above you may any do the following:
- Work on Problem Set 2
- Project 1 Resubmission
Lab 4: Pipes and filters in UNIX
In this lab, you will get to know the commands less and grep, and experiment with input and output redirection.
Lab 4 learning objectives
- Get more comfortable and efficient using the command line
- Use
lessandgrepto view and search through text files - Recognize and use pipe and redirection operators
Icebreaker
Clone our starter code from Classroom 50 into your account on ieng6.
Icebreaker
If you could choose a superpower to have, what would it be? What would you do with it? Who’s your favorite superhero/villain, if you have any?
Please write your names and answers on your whiteboard. No check-off is needed!
Before you get right into more unix commands, we have a quality of life improvement. Recall that in lab2 you made a pair of ssh keys to allow you to securely access github from your ieng6 account. There is another pair of keys we can make which give you the power to never have to type your password when signing into ieng6 again. The tutorial for this resides in the last lab: here.
Searching and Filtering Program Output
In this lab, we’ll walk you through some helpful UNIX commands that are commonly used to save and filter program output. There are multiple ways to achieve the same result, and we’ll demonstrate advantages and disadvantages of each.
In the starter code, you are given a problem.c source code file. This program creates a large 2D array, fills it with numbers, and prints them out.
Fortunately, whoever wrote this was thoughtful enough to write code to check for an out-of-bounds error.
Unfortunately, whoever wrote this was not thoughtful enough to debug the program.
Fortunately, you don’t need to debug this program; we’re going to use this program as an example of how the following UNIX commands can be used to parse a lot of program output easily.
Compile and run problem to see exactly what “a lot of program output” means.
$ gcc -g -o problem problem.c
$ ./problem
Every so often there’s an error message, but it’s separated by all the expected program output. For programs with more errors and more output, you could imagine how we wouldn’t want to keep scrolling up the terminal to read. There are multiple ways in which we can filter out everything but the error messages.
Say Less
In previous Projects, we’ve already used the indirection (<) and redirection (>) operators. These are used to feed input into a program, or redirect the output of a program into a file. Let’s first save the output of the program to a text file:
$ ./problem > problem.txt
Redirection overwrites any content of the destination file with the output. There also exists the append (>>) operator, which works similarly to redirection, but appends the output to the end of the destination file instead of overwriting.
$ ./problem >> problem.txt
You can use cat to view the contents of the file, but this is no better than letting the program output directly to the terminal. Instead, we can say less to start a program to display a portion of the file and navigate freely through it. It’s like cat, but shows less at a time.
$ less problem.txt
The less command succeeds the more command, which does the same thing but does not support backwards navigation. In this sense, less is like more, but also (as man less duly notes) less is the opposite of more.
The one subcommand you need to know is to type h while in this program to display a list of subcommands. Some especially helpful subcommands include q to quit and f/b to move forward/backward one window. You may also notice that you can use j and k to move forward or backward by one line, just like in Vim. The subcommand we want to use to filter out all lines that do not have an error is to type “&” followed by the word “error”, then press Enter. less will insert a slash (“/”) in between to indicate that what follows is a pattern to match. This method of filtering is convenient if you don’t want to clutter the terminal interface, but requires that the output exists in a file already.
Once you have filtered the lines in problem.txt such that only the “error” lines remain, as a team, write the error on your whiteboard. Call over a TA/tutor to get checked off.
Search with grep
The grep command is most commonly used to search for lines of a file that match some string. grep takes in two arguments: the “pattern” to match, and a file to read from.
$ grep error problem.txt
This command directly outputs to the terminal, which can be acceptable if you expect the output to be short, and helpful if you don’t want to run the search as a subcommand within another program, as with less.
Try practicing filtering file contents with message.txt, using either less or grep. This file contains the output of another command, which created a large array, assigned random capital character values, and printed it out. For some strange reason, the output shows that some characters were written way out of bounds at column index 42, but it’s hard to tell what’s happened when each line is separated by all the other output. Use less or grep to search for all lines that contain the string “42”. Are you surprised by what you find?
Flow Like Water
Piping
Both of these methods require you to create a file which contains the output of a file. This is generally pretty easy to do, but can be undesirable if you have a lot of output that you don’t want to be saved into a really large file (or are indecisive about naming files). The solution to circumvent this is to use pipes.
Within industry, piping is a system of pipes used to convey fluids (liquids and gases) from one location to another. Within UNIX, the pipe operator (|) is used to directly feed output from one program as input into another program. We can pipe directly from the problem program into either less or grep to accomplish the same result as running these commands on the problem.txt file.
$ ./problem | less
$ ./problem | grep error
We can compound indirection, redirection, and pipe operators to create helpful commands. Understanding how these operators work in conjunction with each other can be understood as an analogy to actual pipes, rendered below as cool animations.
By default, print statements in programs output directly to the terminal interface. So this command:
$ ./problem
looks like this:
By using the redirection operator, we install an elbow pipe to redirect the flow of output into a file. The output no longer flows into the terminal.
$ ./problem > problem.txt
By using the pipe operator, we install a coupling between the output and input of two programs. Without any other pipes at the end, the output of the second program flow into the terminal.
$ ./problem | grep error
By using both piping and redirection, we can chain multiple commands and file writing actions. In this command, we run the problem program, filter its output with grep, and output the filtered lines into a file. This file now contains the error messages from problem, and can serve as an error log. Does this output to the terminal as well?
$ ./problem | grep error > errors.txt
Having some tee and drinking it, too
Redirection lets us write to a file. Not having redirection lets us directly see the output in the terminal. Why don’t we have both?
By using the tee command, we can simultaneously write output to a file and and continue flowing data rightward, usually to the terminal. tee is a command, not an operator like redirection and piping, so we must pipe into tee first. tee takes a filename as an argument, which it outputs to.
$ ./problem | tee problem.txt
The tee command shares its name with the tee pipe in plumbing. Ironically, tee is not rendered as a tee pipe in this analogy. Did we really research plumbing terminology for this lab writeup? Yes.
We can continue to construct longer pipe systems to feed output through multiple commands. This command runs problem, filters its output with grep, then outputs to both a file and the terminal.
$ ./problem | grep error | tee errors.txt
In the starter code, we’ve given you a compiled select program and lotr.txt. We use this command to select specific columns from an input file that is in the form of a csv, which stands for comma separated values and is commonly used for things like spreadsheets. select’s first argument is how many columns are in the provided csv and the following numbers are which columns it will print:
$ ./select -c 4 1 2 4 < lotr.txt
Notice that the indirection operator (<) goes after the command, rather than before it. While it would be very convenient for us to imagine data flowing from left to right, UNIX requires that the first word be a command or executable. So we comply and pretend that the input flows from right to left initially, then continues rightward into any redirects or pipes.
By using redirection and piping in conjunction with the select program we’ve developed previously, we can extend the abilities of program to not only print out a CSV file, but also to create new CSV files and files with rows that match some condition. Try using redirection and piping in addition to the example command above to achieve these results:
- Save the output to a file named
select_lotr.txt - Filter the output to rows that correspond to hobbits (i.e. lines that contain the string “Hobbit”) and save this filtered output to a file named
hobbit_weapons.txt. Optionally, also print out the filtered output to the terminal. - Could you do both of the above in all one command?
Output Streams
In the examples above, we use redirection and piping to manipulate the standard output (stdout) of a program. By default, printf() outputs to this stdout stream, which we illustrate above. What these diagrams do not show (and will not show, please don’t make me try drawing this) is that there actually exists another output stream for standard error (stderr).
To use stderr, we use an alternative to printf(), fprintf(), and specify that it should output to the stderr stream. In problem.c, this line is given to you and commented out. Uncomment this line, and comment the line above (the original print statement). Recompile and run the program.
$ gcc -g -o problem problem.c
$ ./problem
The output looks the same as before. The default destination for both stdout and stderr streams is the terminal, but this can be redirected. Try redirecting output to problem.txt as we did before. What’s different this time?
$ ./problem > problem.txt
By default, redirection only operates on stdout, leaving stderr to continue to output to the terminal. We modify the redirection to operate only on stderr, leaving stdout in the terminal:
$ ./problem 2> errors.txt
UNIX uses 1> implicitly as the default redirection operator when we just use >. We can read this as “redirect to the stream with file descriptor 1”, where the stream with file descriptor 1 is stdout.
We can also use two redirections in conjunction with each other to redirect different streams to different files in one command.
$ ./problem > problem.txt 2> errors.txt
First, comment back out the
fprintfstatement and uncomment theprintfstatement, so that all output redirects to stdout. Write a command that outputs all lines that involve the first column of the 2D array into both the terminal display and a file calledout0.txt. Write this command on your whiteboard, then ask a tutor or TA to check your work.
The square brackets are special characters in grep, so to search for [ and ], you must use the escape character. For example, if you wanted to search for "[5]", you would use grep like so: grep "\[5\]"
Word on the street is that Column 42 isn’t the only column in message.txt hiding a secret. Time to go find more secrets!
- Open
message.txtin Vim (vim message.txt) and scroll around. It’s a wall of random capital letters, one per line. Quit with:q!when you’ve seen enough, so that nothing you typed by accident gets saved. If you think you changedmessage.txtby accident, rungit restore message.txtto get the original back. - Pick a hint from the table below and work out which column number it points to.
grepfor that number and read the letters from top to bottom. If they spell an English phrase, you found one! If it’s garbage letters, try again.$ cat message.txt | grep 42- Once you find a phrase, save those lines into a file called
grep.txt. Use>for your first phrase, then>>for every phrase after that. Remember,>overwrites the file, so using it again will erase the phrases you already saved! - Find at least 5 phrases (42 doesn’t count, since we already gave that one away). Feel free to find more if you’d like!
grep.txtshould contain only the lines for your phrases: don’t include column 42, garbage columns, blank lines, or anything else, or the autograder will mark it wrong. - Run
cat grep.txtto make sure all of your phrases made it in and nothing else snuck in, then submitgrep.txtto Lab 4 on Gradescope.
Hints
There are two kinds of hints:
- Rows 1 to 5: Each hint is a bitwise expression on hexadecimal numbers. Work out the result, then convert it to decimal to get the column number.
- Rows 6 to 12: Each hint describes a character. The column number is that character’s ASCII value in decimal. Run
man asciiin the terminal to see the ASCII table.
Check off each hint as you find its phrase. The checkboxes are only for you to keep track: nobody else can see them, and they reset when you reload the page.
| Hint | Found it? |
|---|---|
0x10 | 0x03 | |
0x1F & 0x36 | |
0x03 << 3 | |
0x0F ^ 0x15 | |
0x3A >> 1 | |
The C operator that turns true into false | |
The character that starts every #include | |
| The operator that gives you a variable’s address | |
| The character that puts the “C” in CSV | |
The character that starts every absolute path (and every // comment) | |
| The character that stands for the home directory | |
The character '1' (careful: the character, not the number!) |
Lab 5: Finding memory errors with Valgrind
You may find our solutions to the previous labs in our solutions repository. For now, let’s focus on lab 5.
In this lab, you’ll use Valgrind, a memory error checker, to identify memory management mishaps in programs involving arrays and pointers. Valgrind is ubiquitous in systems programming workflows, especially for programs written in C and C++. You’ll find it valuable for future Projects, too!
Lab 5 learning objectives
- Recognize the purpose of Valgrind in C programming
- Interpret output from Valgrind for memory-related problems
- Recognize Valgrind outputs for direct leaks, indirect leaks, use after free, and double free
- Use Valgrind to guide memory error fixing
- Recognize the value of automated tests in software development
- Write automated tests using assert statements
Icebreaker
This week you have the opportunity to write an icebreaker that may be used in future labs! Please write an icebreaker of your own for this lab. One icebreaker from last quarter was: What is your favorite letter? which I encourage you to also answer.
Please make sure that everyone in your group answers the icebreaker and writes their first and last name on the whiteboard. You can add the next activity to the whiteboard alongside these answers!
Warmup: UNIX Golf
Consider “surf” as our starting directory and start there (current pwd). Complete each task in as few keystrokes as possible. Write your answers on your whiteboard then show a staff member.
- Travis listened to Noah Kahan before he was big (totally). Move Noah Kahan to the east_coast directory, and rename him to Noah_Kahan_2024.txt.
- Travis forgot to add Hozier! Add Hozier.txt to less_indie.
- Travis only likes like one or two song from Skeggs. Remove Skeggs.txt
Swap files
If you have ever gone to open your file and encountered the following: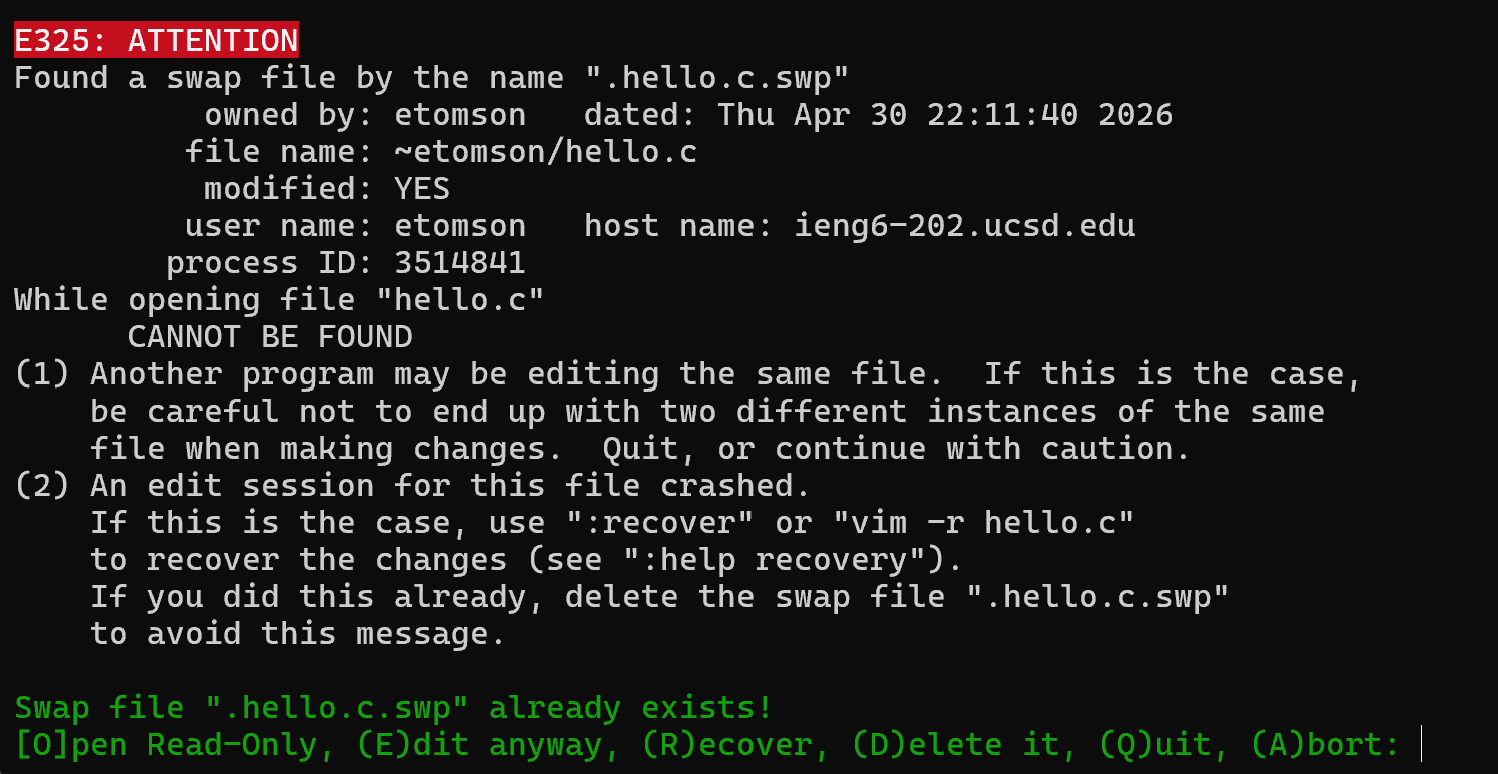
you may have wondered what is going on. This is the menu that appears when you try to open a file but your computer sees that it has an associated swap file. If your terminal crashes for some reason while you are editing it, you computer saves your work in a swap file named as follows: if you had hello.c it will create .hello.c.swp as the swap file (as seen in the picture above). In this file are the changes that it saved for you as it crashed. Reading through the options we find you can:
- Press
Eto open the last save you made. If you are ok with discarding the changes you made after you last:wyou can choose this option. - Press
Rto recover what is saved in the.swpfile. If you haven’t saved recently or simply would like to recover the changes you had made, choose this. After you choose this, you can type:was normal in vim to save these recovered changes to your file.
If you choose the latter option, you will see this menu.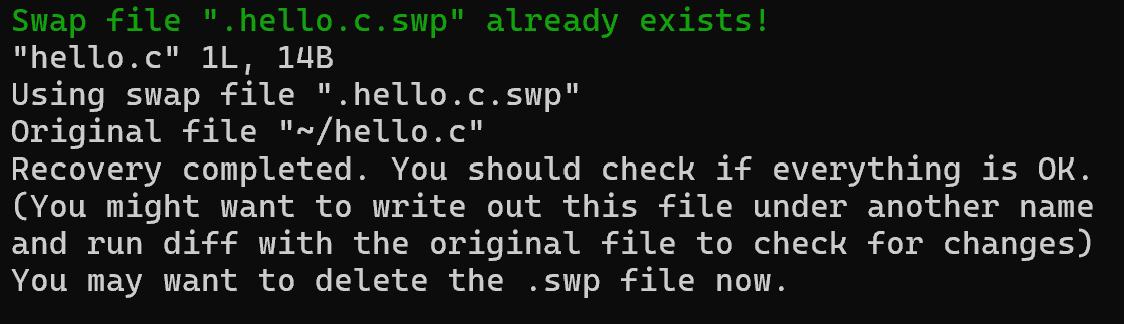
As per it’s suggestion, after you have saved the file and go back to the terminal, you can and should delete the swap file (rm .hello.c.swp for example).
If you choose the former option, you should also make sure to delete the swap file, for fear of later recovering a now out-of-date file.
Some More Vim!
Let’s learn about just a few more Vim commands that might be helpful for the labs and programming assignments.
Moving Up and Down
You may have noticed that moving up and down line by line in a Vim file can be relatively slow. Scrolling up and down the file would be faster!
To scroll down in the file, hold the Ctrl key and press d.
To scroll up in the file, hold the Ctrl key and press u.
Part 1: Help! My program leaks…
Please clone the Classroom 50 Assignment for this lab’s starter code onto ieng6 in your cse29 directory. It contains code for a few programs that leak memory, and in this lab, we’ll use Valgrind to detect these leaks and help fix them. In this repository you will find a Valgrind directory, start here.
Let’s start with leak.c:
$ gcc leak.c -g -Wall -o leak
Remember -g from last week? This flag instructs GCC to add debugging symbols to the compiled executable. These symbols enable GDB to look up and show your source code during debugging. They also enable Valgrind to show you line numbers in its error backtraces.
Take a moment to review leak.c and predict what it should print, then run ./leak. Although running the program gives no visible errors, the program actually produced some memory leaks as a result of us not properly freeing the allocated memory. The Valgrind program allows us to see how much memory is still being used when the program exits, and therefore leaked. Like with GDB, you pass in the program to inspect as an argument to valgrind.
$ valgrind ./leak
We see a suggestion from valgrind to add --leak-check=full flag to instruct Valgrind to report the locations where leaked memory had been allocated:
$ valgrind --leak-check=full ./leak
Valgrind provides a “heap summary” of how much memory is still being used at exit, and a “leak summary” which details the different types of leaks that have occurred. When Valgrind reports anything in a leak summary, that means you have a memory leak! Memory leaks are especially harmful in long-running programs, where the amount of available memory gradually reduces over a long time, thereby also reducing the overall performance of the program or the computer in general.
Because we supplied the --leak-check=full flag, Valgrind also printed the stack trace at the instant where each chunk of leaked memory was allocated. You might be inclined to think that the problem lies around the line number it references, but this is usually not the case! Valgrind is just pointing out where the leaked memory got allocated. You, the programmer, decide where it is supposed to be freed. Sometimes, the appropriate place for a free call can be far away from its malloc call in your source code.
Types of Memory Errors
Unlike real life (plumbing) leaks, it’s okay to leave the (memory) leak in leak.c alone for now; we’ll come back to it later.
“Did 👏 you know 🚫😱 that 🙇🚟 memory leaks are especially harmful in 🙌 long-running programs, 📺 where the amount 💀 of available 💢💢 memory gradually reduces over 😈😏 a long time, 🕐 thereby also 👨 reducing the overall performance of the program 📺 or the computer in 👏🏡 general.” ~ Aaron
In memory_errors.c, we demonstrate some common situations in which memory errors can occur. Rather than manually writing the compilation command, we’ve provided a Makefile for you to use. This will be helpful since we have quite a few files to compile in this lab. To compile a program, use the make command followed by the name of the file to compile without the .c suffix. For example, to compile memory_errors.c into the memory_errors binary file, use this command:
$ make memory_errors
In order to see more details of the leaked memory, make sure to add the --leak-check=full flag.
$ valgrind --leak-check=full ./memory_errors
With this flag, the Valgrind heap summary will also report the locations where leaked memory had been allocated, since we compiled the program with the -g flag.
Let’s go over each function in memory_errors.c in more detail, and fix each of them:
memory_leak(): In general, memory leaks occur when we allocate memory and do not free the memory before the program exits. Here, we fix the memory leak by callingfree()on the pointer returned bymalloc()which points to the allocated memory.free_after_set(): In this case, we lose the pointer to the allocated memory when we set it toNULL, therefore callingfree(p)does not do anything. In general, we consider it good practice to set a freed pointer toNULL, but it actually needs to be freed first! We can fix this by making sure to callfree()on the pointer before setting the pointer toNULL, instead of after.double_free(): This one isn’t actually a memory leak, but it’s an error that can occur with improper usage offree(), which is why it’s here. Callingfree()on a pointer that has already been freed is considered undefined behavior, meaning that it should not be expected to work properly. This program gives you a really messy memory error when you try to run it. Valgrind will also report an “invalid free” error above the heap summary. In this case, it’s apparent why the double free error occurs and how to fix it, but in other cases it may be more obscure.reuse_freed(): Also not a memory leak, but a case in which we try to access memory that was already freed. Valgrind reports this error as an “invalid write” above the heap summary. Again, it’s good practice to set a freed pointer toNULLimmediately after it’s been freed.double_malloc(): This can accidentally occur when you intend to allocate two blocks of memory to be used one after the other with the same pointer, but forget to free the first block. What should be done here to fix this leak?
Once you’ve implemented the fixes, compile and re-run the program with Valgrind to confirm that there are no longer any memory leaks or errors. It should report that “all heap blocks were freed – no leaks are possible”. Yippee! Although if there are still memory leaks/errors, try again, then yippee.
Types of Memory Leaks
You might have noticed in the leak summary of Valgrind that there are different types of memory leaks. The distinction between these leaks isn’t too important for our purposes, but may help you identify how leaks are happening in a more complex program.
In leak_types.c, we demonstrate each of the different types in separate functions. There’s no need to fix these leaks; just compile and run Valgrind on the program to see how Valgrind reports different types.
$ make leak_types
$ valgrind --leak-check=full ./leak_types
Notice how the heap summary gives you information on where each memory error occurs. Inspect the source code to see how each type is caused.
- Definitely lost: Besides myself, memory leaks are also considered “definitely lost” when the pointer to the memory becomes inaccessible. This can happen when the pointer is deleted when a function ends and its stack frame is deleted, or when the pointer is set to another value.
- Indirectly lost: Blocks of memory are considered “indirectly lost” when there exists a pointer in another leaked memory to the block. In this case, the memory pointed to by
pp(i.e.*pp) is definitely lost, and the memory pointed to by*pp(i.e.**pp) is indirectly lost. - Possibly lost: “Possibly lost” memory leaks occur when we have a pointer to some part of the leaked memory, but not to the base of the memory block, likely because the pointer was modified. In this case, we allocate an array of integers, then move the pointer to point to the middle of the array.
- Still reachable: Memory leaks are “still reachable” when the pointer is not lost when program exits, but the memory is still unfreed. This can occur when a global variable contains a pointer to leaked memory.
- Suppressed: Users can specify the flag
--suppressions=<filename>to Valgrind to intentionally ignore leaks that are known to be harmless or unavoidable. If you want to learn how to use this flag, you can check out this StackOverflow post, although in our (at least one old tutor and at least one old TA) experience this flag is seldom used, if at all.
Valgrind on Arrays
Now let’s put what you’ve learned into practice. In the lab repository, leak.c and losing_track.c have memory leaks. You will identify and fix the problems in each program. Work with those around you!
In leak.c, there is a function that performs matrix addition on two 2D arrays. While the functionality may appear correct, a run of valgrind will tell you that memory isn’t freed properly. For reference, here is a diagram of how matrix addition works:
Please check in with your teammates to make sure everyone understands leak.c and it’s problem and solution. If you have any questions now is a good time to ask a staff member as a group for any clarifications.
In losing_track.c, there is a function that returns the lower-cased version of the query string of a url without modifying the original string. This is the portion after the question mark in http urls that are often used to specify parameters for a website. We want to return this portion without modifying the original URL. Like previously mentioned, this function appears to work properly, but does not manage memory properly. This error is particularly nasty because this implementation loses track of its allocated memory. Let’s take a deeper look into what this means.
When we first initialize query, we point to the beginning of the string, and therefore have access to our whole chunk of memory. Our memory looks like this:
However, after we convert the string to lower case, use ptr to traverse through the string, and return ptr, we no longer have access to the beginning of the string, and therefore can’t free the chunk of memory!
Describe the problem and how you would fix it. Work with your teammates and write this on your whiteboard. Do leave yourself space to add 2 more similar descriptions and fixes.
Given time, you may implement the solution and check your work however implementing your solution is OPTIONAL. If you would like to implement your your solution, note that given this is a very involved change, please modify the method as much as you like!
HINT: the problem of the current implementation is that in the string we return, we don’t keep track of the beginning of the string. How can you change this code so that the string we return has its pointer pointing to the beginning?
Valgrind on Structs
As we prepare for our later projects, let’s see how Valgrind can help us discover more memory problems. Compile log.c and run it with Valgrind using the same flags from above. In this case, it should report that 372 bytes of memory have been leaked. Follow the stack trace shown by Valgrind to contextualize yourself with the “story” of the lifetime of this chunk of memory. When did it get allocated? When do you think it should’ve been freed? How can you fix it?
A common misconception is that we can free memory by redirecting pointers to that memory to NULL, the null pointer. You can draw a memory diagram to see that this won’t actually free that memory. Edit log.c so that the main function calls free_log instead of setting ourLog to NULL. Did this fix the leak?
Once you recompile and re-run with Valgrind, you should see a different error: Invalid read of size 8. This time around, Valgrind has a richer story to tell about this chunk of memory. Read the series of backtraces from the bottom line upward to see the events that took place in chronological order along with where they were triggered. Use this story to help understand the nature of the memory problem and figure out how to fix it. You can also pull out GDB if you’d like.
Once you fix this error, re-compile and re-run the log program with Valgrind, and make sure that Valgrind reports no errors and that “no leaks are possible”. Add the problem and solution to the whiteboard.
This is an example of “use after free”, accessing a chunk of memory after you have freed it. The program might still have worked prior to your most recent fix, but because it accessed and relied on data inside a chunk of memory after it was freed, the program was subject to undefined behavior—it could crash, corrupt other memory it owns, or do whatever it wants! Thankfully, Valgrind can detect most instances of undefined behavior and help you eliminate it.
“Double free” is a specific kind of “use after free” where a program tries to free a chunk of memory that has previously been freed. Let’s see how Valgrind reports instances of “double free”. Duplicate the call to free_log in main, and recompile and rerun it with Valgrind.
In addition to Invalid read of size 8, where free_log attempts to access the title and content member of a freed struct day, Valgrind also reports Invalid free() / delete / delete[] / realloc() arising from the first free() call inside free_log. Now you know!
Valgrind and uninitialized values
Another source of undefined behavior is reading from uninitialized memory. Valgrind can detect this, too! Compile writesong.c using the same flags as above, but now, run Valgrind with the following:
$ valgrind --track-origins=yes ./writesong
The program should write a simple song to mysong.txt using file I/O operations you will also encounter in PA 2. However, Valgrind reports several instances of “Conditional jump or move depends on uninitialised value(s)” and “Use of uninitialised value”, and because we included the --track-origins=yes flag, it shows us where each uninitialized value was declared. The reports seem to repeat, indicating that an uninitialized value was used in a loop. Read the contents of writesong.c to figure out the problematic variable and initialize it properly. Verify that Valgrind no longer reports these errors when you run the program.
You should now be able to tell if you’ve fixed the memory problem on your own! Add the problem identified and how you fixed it to your whiteboard.
Make sure to call over a staff member to go over your plan for how to fix the memory leak in losing_track.c, log.c, and writesong.c that are on your whiteboard.
As we have seen, Valgrind is useful for discovering memory bugs in your program. This will be especially useful in projects where you will be graded on proper memory management as you query and sort various data. Alongside Valgrind, we cannot understate the usefulness of drawing memory diagrams in helping you reason about memory management and fix memory issues. They make memory management much more intuitive, so embrace them!
Part 2: Exposing bugs via automated testing
In this section, you will put your GDB and Valgrind skills into practice by finding and fixing bugs in an scheduling program. You’ll also learn to write unit tests using assert statements to expose bugs. We hope that our introduction to testing helps you with writing your own tests in your projects!
Unpaid SWE Internship Experience
Congratulations on landing your first internship! It’s been a long road filled with leetcode sessions, piles of rejections, and empty containers of your caffienated drink of choice, but it must all be worth it for this experience. Your first assignment jsut came in from your boss:
Hello, dear Intern, I am the lead for our organization’s new and improved Course Registration and Appointment Platform! It’s practically a perfect system (except for a couple teeny tiny bugs) and has all the bells and whistles ready to ship (like a working weekly calendar)! However, there are those little bugs that do need fixing, and sitting around all day really tires me out, so I’m tasking YOU with handling those bugs. This is your first assignment, so try not to dissapoint!
Sincerely,Ben Schwarmer
You will be testing some bad implementations of some functions and finding out what’s wrong with them. Some of these implementations have memory leaks, others may be logically incorrect, and some of them just straight-up crash on certain inputs. It’s up to you to use all the tools in your debugging arsenal and all the knowledge you’ve gained to pick out the exact problem(s). Head to the Testing directory which is adjacent to Valgrind. Check out the schedule.c file to take a look at the code you’ll be critiquing.
We will stick to the following step-by-step process to remove defects from this file:
- Write tests that expose an existing bug by failing, which can take the form of:
- An “Assertion failed” message
- Memory errors when the test is executed with Valgrind
- A program that never terminates
- Use Valgrind and GDB to inspect how the tests failed
- Implement a fix such that the tests pass
Bad Clear Schedule
Given some argument arg, it checks if arg is true. If true (nonzero), it returns normally, and the code after the call to assert proceeds. If false (zero), it crashes the program immediately with an error message that includes the line number of the failing call to assert. While we can use the assert function to verify assumptions about our program, it is also essential in automated tests. assert function calls in automated tests check for an expected outcome. For example, a test may conceptually sound like:
If I create an empty list, and I then call
add_courseon this list with(29, 4), then (I assert that) the list should now contain one course withcourse_idequal to29andunitsequal to4.
Let’s start with test_clear_schedule_1. Around line 131 in schedule.c, we have written an example test for you. Compile schedule.c with the -g flag, and run it with Valgrind. Identify and make your fixes to make our test pass with no errors from Valgrind. Feel free to write more tests to check more cases.
Test-First Development
Feel free to skip this note and come back to it later.
Most programming courses in higher education adopt a “Test-Last” approach, where we first write the implementation and then write tests to verify its correctness. What if we flip this order? The Agile programming community has advocated for Test-First Development (TFD), where whenever we want to develop a new feature, we first write tests (that would obviously fail), and we then write the implementation with the goal of making the tests pass. While this sounds counter-intuitive, following it in a disciplined manner has several benefits for software engineering:
- TFD promotes high test coverage, meaning tests exercise many (if not all) parts of your implementation code
- TFD encourages you to refactor your code, i.e., restructure it for performance, maintainability, etc. without worrying that you might break something because you can easily find out by running your tests
- Some argue that TFD makes programming more fun and rewarding. Writing a test is like giving yourself a challenge, and seeing it pass for the first time is gratifying. On the other hand, writing tests last can seem like a chore.
However, TFD is criticized for its counter-intuitiveness, repeated context switching between testing and implementing, and being unsuitable for input/output applications. While we are not in a position to officially recommend Test-First Development, we want you to try it with your next PA and see if you like it.
Now that we have seen how an assert works for writing a few test cases and catching bugs, we shall write our own. We have given you 2 broken functions, bad_drop_course and bad_copy_schedule.
Bad Drop Course
There are 2 problems with bad_drop_course in schedule.c. One will be caught by Valgrind, and the other we will have to find using asserts. Write assert statements to test this function, including one which should fail. Some test cases we usually want to consider when dealing with lists are what happens at the beginning, the end, and somewhere in between. Here’s an example test you could write:
- Create a schedule and add courses 12, 21, and 29 (with 4 units each).
- Use
bad_drop_courseto drop the first course, 12 - Assert that the first item of the list is now 21
- Assert that the second item of the list is now 29
- Assert that the third item of the list is NULL
Now that we have successfully found in which case the program does not give us the desired behavior, it is easier to pinpoint where in the code there is a problem.
Bad Copy Schedule
At this point, you are probably getting bored of the uninspired section names. What we hope you haven’t gotten bored of is writing tests, because that is what you will be doing yet again.
The bad_copy_schedule function should take in a schedule and return a pointer to a deep copy of it. This means that if we were to add or drop a course from either the schedule or the copy, it should not affect the other. For example, if we are given the schedule [12, 21, 29], and we copy it, the copy should look like [12, 21, 29]. If we drop a course (say 21) from the original schedule, it should look like [12, 29, NULL] while the copy stays the same. For another example, say you have that same schedule and copy it again. Then if we use clear_schedule on the copy, it should be empty while the original schedule is unchanged.
Use these examples to help you write tests that expose the bugs in bad_copy_schedule.
After finding the bug, now you should be able to debug the code and implement a working solution.
You must also fill out this mid-quarter survey.
Submit your repository to gradescope!
Notes on the autograder:
- Tests must go in the four test functions; anything written in main is ignored.
- Students have to add the missing frees to the example test, because the leak check covers it too.
- The structs and function names must not change. (edited)
You must also fill out this mid-quarter survey.
Next steps
If you finish with the lab content above you may any do the following:
- Go back to the “On your own time!” sections and do them.
- Work on Pset3
Lab 6: Automating compilation with Makefiles
You may find our solutions to Lab 5 in our solutions repository. For now, let’s focus on lab 6.
In this lab, you will review structs, fix a memory leak, learn about the syntax of Makefiles and write a couple Makefile rules.
Lab 6 learning objectives
- Interpret and understand Makefile syntax
- Write a simple Makefile rule with dependencies and a recipe
- Review the behavior of bitwise operations
Icebreaker
What is your dream concert lineup?
Please make sure that everyone in your group answers the icebreaker and writes their first and last name on the whiteboard!
Warmup
The warmup for this lab will be projected on the screen. The slides will be posted HERE once all labs have concluded.
Here is the classroom 50 assignment for this lab.
Part 1: Search and Makefiles
You are given a Makefile with the default set to compile the provided program. You should only need to run make to compile.
To run search, you must provide an argument of the substring to search for, ie:./search alpaca < rockyou_clean.txt will search through the rockyou_clean.txt file line by line, printing out lines containing “alpaca”. Note this file can be found at /home/linux/ieng6/CSE029_FA26_001/public/rockyou_clean.txt
The program prints “Malloc returned NULL” if it’s malloc call ever returns NULL.
As ieng6 is a very large and powerful machine, the limit on how much of it you can use is very high — but not infinite. Let us now test the limits of ieng6.
Using rockyou_clean.txt’s even longer cousin, long_rock.txt which can be found here /home/linux/ieng6/CSE029_FA26_001/public/long_rock.txt. Increase the requested size in the malloc call until you receive the message “Killed” when searching for a word in the file. Each team member should contribute one value which results in “Killed” and one which does not (Brownie points if you narrow in on the threshold) to your whiteboard.
Leave plenty of space for the next answers like this ^
We receive this “Killed” message when ieng6 determines we are demanding too much of it. It has the user limit (ulimit) set to unlimited. Run ulimit -a to see the data segment is set as such. We can set this to be more limited by running ulimit -d 100000.
Restore your search.c to it’s original state (recall git restore?).
Now if we run our search program on the long input again we should see Malloc return NULL.
What does valgrind say if you run it on your search program now?
To reset your limit, reconnect to ieng6.
Have each person in your group search for a different string in long_rock.txt using valgrind, how many bytes does it report as being in use. Do your answers make sense?
Add this to your whiteboard as shown above and call over a staff member to check you off.
Makefiles
Part 0: Recipes and Dependencies
Enter the part0 directory. We have given you an example Makefile that illustrates its basic structure. A Makefile mostly consists of “rules”, which have the form:
target: dependencies
    recipe
In a lot of ways, you can think of defining rules in Makefiles like defining functions in C, but there are important differences.
- The target could be thought of as the name of the rule. We use the target to tell
makewhich rule should be used. Unlike functions, Makefiles expect targets to be the names of files. - The dependencies are files or other targets that the creation of the target depends on. For C programs, these dependencies are usually source code and object files.
- The recipe contains the commands that are executed when
makeuses this rule. Recipes can have one or more different commands to be executed sequentially.
Use this explanation to understand the contents of the Makefile in part0. Try running make with the cse100 target to ask Make to build cse100 along with its dependencies:
$ make cse100
Pretty cool! It might also be useful to clean out and remove any files that got produced if we want to run make again, like all the cse files that we just made in this Makefile. We do that using:
$ make clean
This will remove all the files that start with cse. Now, after running make clean, we can run:
$ make cse30
$ make cse100
See what files get made at each step! Try out the other targets as well, like cse12 and cse29.
Part 1: Makefile for One
Exit the part0 directory and enter the part1 directory, where we are given a single, very simple source code file program.c. You can look at its contents, but there’s nothing there to see (or do).
It’s not necessary to define dependencies, but we often do because Makefile automatically checks if any of its dependencies have changed more recently than the target file. If not (and if the target file already exists), then make does not bother to execute the recipe, because the target file must already be up to date. This means that make will only execute the recipe if the target file doesn’t exist, or one of its dependencies is more recently updated than the target file.
A typical example of a rule for C is the one below:
program: program.c
    gcc -Wall -g -o program program.c
In this rule, the target is program, which is the executable file we want to create with this rule. The recipe is a gcc command to produce program, which you would normally run manually in the terminal. Since we define program.c to be a dependency of this rule, this means that program will only be recompiled if program.c is more recently updated than program.
This rule example just so happens to work perfectly for the Makefile we want to write in this section, so fill in your Makefile with this rule. Please note you should create your Makefile, for example, using the command touch Makefile.
After writing this rule into the Makefile, you can then run make with the target to run the compilation command in the recipe:
$ make program
Notice that make prints out the recipe command, and, if you check the contents of the directory, executes that command to compile program.c. Try running make program again to see that make refuses to recompile program, because it’s already up to date. Then make a small change to program.c, and run make program again to see that it recompiles if program.c is changed.
This Makefile has already greatly simplified our workflow: instead of typing 33 characters to compile the program, you can type just 12 characters instead. But we can do even better! Add the following rule to the top of the Makefile:
default: program
This rule creates the default target with the program target as the sole dependency and no recipe. Since it is the first rule to appear in the Makefile, running make by itself will default to executing it, which in turns executes the “program” rule as needed. Technically, you could rename the target from default to something else, and the behavior of the make command by itself would stay the same.
Running and Cleaning
Although recipes typically contain commands used to create their corresponding target files, recipes can also contain any other commands you could run in the terminal. As such, some other common uses for Makefiles are to run a program and clean up after a program.
For this program, the rule for running program could be defined as:
run: program
    ./program
This simple rule depends on the program target, meaning that it will automatically recompile program if necessary, and run the program. In this case, the target is not a file that we expect to compile, just a convenient name that we use to use this rule.
Similarly, we also often define a rule to clean up files that are produced from the build process. This specific example does not produce any, but sometimes it is also desirable to clean up the target file itself in order to recompile without changes to the source code.
clean:
    rm program
In most cases, this will work without issue, but in the rare case that you create a file called “run” or “clean”, the corresponding rule won’t work properly anymore. This occurs because make does not recognize that “run” and “clean” are not supposed to be files. So when a file of that name is created, the standard behavior of make causes our intended functionality of these two rules to fail: make will not use these rules unless that file no longer exists or a dependency updates. If you want to, try making a file called “run” or “clean” to see this happen.
In order to account for this edge case, we can manually define run and clean to be phony targets. A phony target doesn’t really refer to a file; rather it is just a recipe to be executed when requested.
.PHONY: run clean
After defining these rules, your Makefile might look something like this:
default: program

program: program.c
    gcc -Wall -g -o program program.c

.PHONY: run clean

run: program
    ./program

clean:
    rm program
All the rules (and phony target definition) can be defined in any order, except default must be placed at the top in order to be executed when you run $ make by itself.
Part 2: Makefile for Many
In this section, we’ll show multiple valid Makefiles for the programs in the part2 directory. As you follow along, pick one and use it to compile all three programs.
When we have multiple programs to be compiled in a single project, we could create a Makefile with rules for each:
default: program1 program2 program3
program1: program1.c
    gcc -Wall -g -o program1 program1.c
program2: program2.c
    gcc -Wall -g -o program2 program2.c
program3: program3.c
    gcc -Wall -g -o program3 program3.c
Notice how much repetition there is between each rule here. In this case, the repetition is just mildly annoying, but if you have more independent programs (like I do when designing lab activities), mildly annoying becomes very annoying! We’ll see how we can reduce repetition in two different ways that we’ll use together to create a very concise and flexible Makefile.
Variables
Like in C programs, you can also define variables in Makefiles. But unlike C programs, where defined variables are allocated in some memory when the program is run, variables in Makefiles just represent some string value. This lets us reduce the amount of repetition when we want to, for example, change the gcc flags to use in all rules. As such, some common values we can define as variables are the compiler command and its flags:
CC = gcc
CFLAGS = -Wall -g

default: program1 program2 program3

program1: program1.c
    $(CC) $(CFLAGS) -o program1 program1.c
program2: program2.c
    $(CC) $(CFLAGS) -o program2 program2.c
program3: program3.c
    $(CC) $(CFLAGS) -o program3 program3.c
The variables CC and CFLAGS are defined with the values gcc and -Wall -g, respectively. Then we use these variables in each of the recipes. Note that there is a special syntax when we use the variables: $(X), where X is the variable name. This syntax tells the Makefile to expand the variable X to use its value, instead of interpreting “X” as a literal string.
Pattern Rules
Each of these three rules have a similar pattern: each one is identical to the others except for a single number that changes. To eliminate this repetition, we can merge these rules into one pattern rule:
CC = gcc
CFLAGS = -Wall -g

default: program1 program2 program3

program%: program%.c
    $(CC) $(CFLAGS) -o $@ $<
A couple of new symbols were introduced in this pattern rule:
-
A target with a “%” character creates a pattern rule. The “%” in the target can match any non-empty string, then for each corresponding match, the “%” has that same value in the dependencies. For example, this rule matches
program1,program2, andprogram3and defines their respective dependenciesprogram1.c,program2.c, andprogram3.c. This will also define dependencies for any valid match to the target:program4depends onprogram4.c,programaaadepends onprogramaaa.c, etc. -
In a pattern rule, we use automatic variables to refer to the target and dependencies, since their exact value is not determined explicitly.
$@is an automatic variable which represents the target of the rule.$<is an automatic variable which represents the first dependency of the rule.
Other useful automatic variables are given here.
If we were really bold (which we are), we could generalize this Makefile further:
CC = gcc
CFLAGS = -Wall -g

default: program1 program2 program3

%: %.c
    $(CC) $(CFLAGS) -o $@ $<
This pattern rule now matches any name (not just names that begin with “program”) to be a target, and defines its dependency to be a file with that name plus the “.c” suffix.
In this section, we’ve developed a Makefile to be increasingly more flexible, both in making future changes easier and expanding the scope of valid targets. An important point to make (pun intended?) is that each of these Makefiles is a valid Makefile for compiling the three programs given in this directory, and they have their own pros and cons. For example, a Makefile similar to the last one was used in last week’s lab to easily compile programs with different names, where the compilation process is the same across programs. However, it might be undesirable to enable the programmer to attempt compiling any file ending in “.c”. On the other hand, the first Makefile might be a good fit for a use case where we know we will customize the build process for each program, but this could lead to a very large Makefile.
Part 3: Linking Object Files
When we use gcc to manually compile programs, we typically compile directly from the source file to the executable program. But, the build process involves multiple steps with intermediary files. One of these intermediary files are object files, which contain machine code from a particular module (.c and .h combo) and are linked into the eventual executable file. If .class files from Java sound familiar to you, object files are like .class files. To instruct gcc to compile a source file into an object file, we add the -c flag.
(Credit: Cloudflare)
The linking process resolves symbol references between object files, meaning that functions defined in one file can be used in another. In part3, a long program with 50000 adder functions (each of which adds the integer in its name to the parameter and returns it) is given in adders.c. The corresponding header file, adders.h, contains function declarations to be shared between source files. Then, in main.c, we print the return value of run_adders, which calls all of the adder functions and sums their results.
We can use the following gcc commands to create then link the object files (we will run the time command so it will tell us how long each of these commands took to run):
$ time gcc adders.c -o adders.o -c
$ time gcc main.c -o main.o -c
$ time gcc adders.o main.o -o adders
We create adders.o from adders.c, create main.o from main.c, then link the two produce the executable adders. My fingers hurt from all that typing; I wish there was an easier way to MAKE all these files…
CC = gcc
CFLAGS = -Wall -g
TARGET = adders
OBJS = adders.o main.o

default: $(TARGET)

adders.o: adders.c adders.h
    $(CC) $(CFLAGS) -c -o $@ $<

main.o: main.c
    $(CC) $(CFLAGS) -c -o $@ $<

$(TARGET): $(OBJS)
    $(CC) $(CFLAGS) -o $(TARGET) $(OBJS)

run: $(TARGET)
    ./$(TARGET)

clean:
    rm $(TARGET) $(OBJS)
Here, we make extensive use of variables for the ultimate target (adders) and its prerequisite object files (adders.o and main.o) so that we can easily use these strings in multiple places, e.g. in both the compile command and in the rm command. Examine this Makefile and feel free to ask your groupmates, tutors, or TA about anything unclear.
Go to the one_million_functions directory and take a look at the script.sh file (a bash script, which we learned about last week).
This runs very similar commands to the time commands you ran previously to compile the adders program. This example, however, has one million functions as opposed to the original fifty thousand.
To run a program in the background we can add a & immediately following it.
$ ./script.sh > out.txt &
for example, will write to our output file and do so in the background, meaning you can use your terminal in the meantime. You can check on this periodically by using cat to see out.txt, go ahead and see what it has immediately after starting your background process.
Part 4: Makefile challenge
Go to the part4 directory and open the Makefile there, which is partially completed. Complete the Makefile according to the requirements listed inside it. Feel free to copy code segments from above. Once you’re done, try make to see your Makefile in action!
Submit your finished repository to Gradescope!
Next steps
If you finish with the lab content above you may any do the following:
- Do the lab 7 preview below.
- Work on Project 3
- Learn something new about unix/ systems and share with people around you.
Lab 7 Preview: Hacking
7.1. Background
Imagine that you’re a less ethical student than I’m sure you actually are. You overhear from some other students in lab that there’s a binary available on the pi-cluster that can show you your grades on assignments before we formally release them. You hear quieter whispers that someone found a way to use it to change their grade. Given our less-than-ethical assumption about your state of mind, you might be tempted to exploit this for yourself.
7.2. The Plot Thickens
You see some code open on the professor’s laptop during office hours. You do
your best to commit it to memory and write it down (remember, you’re acting
quite unethically in this story), because it strikes you that the code was
something regarding assignment scores.
Using this information, you decide to give yourself and A with a score
to match while maintaining a real due date.
HINT
When important values are adjacent on the stack, overflowing an array with
values that you control can let you assign into other stack-allocated values.
GDB commands that may be useful for this activity:
-
(gdb) info locals -
(gdb) info args -
(gdb) print VALUE (or p VALUE)You can print any variable or expression, e.g. -
print x,p arr[5],p ((x & 0b1111) << 3) -
You can also specify a format to print in
-
print/t(binary),print/x(hex),print/d(decimal) -
(gdb) x ADDRESSThis prints out memory at an address, e.g. strings / arrays / pointers -
(gdb) x/16cb str1This prints the first 16 bytes ofstr1as characters -
(gdb) x/20xb str2This prints 20 bytes ofstr2in hex -
(gdb) x/4dw arrThis prints 4 “words” (i.e.int32s) ofarr, as decimal numbers -
You can use the following reference card for reference on gdb commands, and format commands for x and print.
Lab 7: Shell scripting, Buffer Overflow, and Workspace Configuration
In this lab, you will hack a gradebook to give yourself an A on an assignment, and organize some nostalgic files using shell scripting.
Lab 7 learning objectives
- Understand how buffer overflow works and why it is bad
- Understand the utility and overall mechanism of shell scripting
Can you guess what part of campus each of these photos was taken? Work with your groupmates! Google Maps is allowed!

Please write the answers on your whiteboard!
Configuration files to improve quality of life
SSH Config
In this class, we mostly use the ieng6 server. However, in the future you might have access to multiple servers for which you want to create separate SSH keys. To help us keep track of our SSH keys, we can create a configuration file called an SSH config file.
Exit the ieng6 server one more time, and create this SSH config file inside your .ssh directory that is in your home directory on your computer.
$ vim ~/.ssh/config
If on windows you can do notepad ~/.ssh/config
It may create the file as config.txt and you will need to rename it to config
Copy the following lines and paste them into the config you just created and opened.
Host ieng6
    HostName ieng6.ucsd.edu
    User <username>
    IdentityFile ~/.ssh/id_rsa
The default place for the private key is ~/.ssh/id_rsa so this particular IdentityFile line is unnecessary. If when you use ssh-keygen you do specify a filename for your keys, this is how you would use it for a particular host. (you could have named it key-to-ieng6 and then you would simply put the path to that new private key in the config)
Replace <username> with your ieng6 username. The IdentityFile field specifies the filename for the private key created to access the given server.
Now try to login to your ieng6 account again. This time, you can type the ssh command in a shorthand form using the name provided in the ssh config file after Host, which is ieng6 in this case.
$ ssh ieng6
This configuration file can contain many entries to manage access to multiple sets of ssh keys for various servers that you might have access to in the future. And it will save you some typing also. How nice!
Custom Configuration
So far, we have seen that Vim commands can be manually typed in an open Vim window, however this can quickly become repetitive if you commonly want to execute the same commands every time you open a new Vim window.
Alternatively, we can tell Vim to execute a certain set of commands automatically every time we open a Vim window in the future. For example, we can type a command to enable syntax highlighting in Vim, which will add syntax-specific coloring to your code and will vastly improve your experience reading through code in Vim. Another Vim nicety we might want to enable is adding line numbers to the file. There are many, many different commands and settings that we can enable and configure to create our own personal Vim experience, which will make writing code in Vim much more enjoyable!
We can do this by putting these commands directly into a Vim runtime configuration file, called a .vimrc file.
The . prefix means that it is a hidden file in UNIX, also commonly called a dotfile. This means that these files will not display, by default, when listing the contents of a directory (using the ls command).
By convention, you will create the .vimrc file in your home directory: ~/.vimrc
Remember: the tilde character ~ is a shorthand for the current user’s (your) home directory in UNIX.
Editing your .vimrc
We provided you with a .vimrc file in lab 1
Using Vim, open the .vimrc file in your home directory on your ieng6 account:
$ vim ~/.vimrc
You will see the following lines into your empty .vimrc file, as shown in the code snippet below:
syntax on
set number
set belloff=all
set showtabline=2   " always show buffer tabs
set tabstop=4
set noexpandtab   "ensures tabs do not expand to spaces
set autoindent
set cindent
inoremap { {<CR>}<Esc>ko
set shiftwidth=4
set backspace=indent,eol,start
The effect of each of these commands is summarized briefly below:
syntax on: enable syntax highlightingset number: display line numbers in Vimset belloff=all: disable Vim bell soundsset showtabline=2: always show buffer tabsset tabstop=4: set tabs to be four spacesset noexpandtab: does not expand tabs to spaceset autoindent: apply indentation to next line based on current lineset cindent: apply indentation with respect to C code syntaxinoremap { {<CR>}<Esc>ko: autocompletion of curly braces for ease of useset shiftwidth=4: Ensures the size of indentation when using<<or>>in normal mode is 4 spacesset backspace=indent,eol,start: Allows you to backspace over automatically placed indentations, line breaks, and text entered before entering insert mode
If you find yourself ever working with python, you may want to switch set noexpandtab to set expandtab. Python cannot handle having mixed tabs and spaces and will error with the message TabError: inconsistent use of tabs and spaces in indentation.
If you have set noexpandtab set and edit a python file that uses spaces, this will occur. For our future purposes we need to have real tab characters for when we learn about Makefiles!

In general, you should not paste a command into your .vimrc if you are not sure what it is doing. But you can definitely trust us! :D
These are our suggestions for .vimrc settings that we think are helpful for you in this class. If you feel like you don’t like some of these features, feel free to remove the corresponding lines in the .vimrc file. These configuration files are usually customized to each programmer’s preferences—figure out what works well for you!
One customization that we have not added that we highly encourage you to check out is :color <color> you can open a file and type :color and press tab to toggle through the available options OR you can see the list of available colors on ieng6 in the /usr/share/vim/vim91/colors directory.
HACKING
Start by cloning our classroom 50 assignment into your ieng6 account, as usual.
Background
Imagine that you’re a less ethical student than I’m sure you actually are. You overhear from some other students in lab that there’s a binary available on the pi-cluster that can show you your grades on assignments before we formally release them. You hear quieter whispers that someone found a way to use it to change their grade. Given our less-than-ethical assumption about your state of mind, you might be tempted to exploit this for yourself.
The Plot Thickens
You see some code open on the professor’s laptop during office hours. You do
your best to commit it to memory and write it down (remember, you’re acting
quite unethically in this story), because it strikes you that the code was
something regarding assignment scores.
Using this information, you decide to give yourself and A with a score
to match while maintaining a real due date.
HINT
When important values are adjacent on the stack, overflowing an array with
values that you control can let you assign into other stack-allocated values.
Given the variable names as seen in the source code shown above, you can use the GDB commands below to give you information about how the memory is laid out.
A recommended place to start is by typing a very long comment and then using GDB to print values around the variables in the struct called assignment to see where the values ended up.
Remember to work together and that the staff is there to answer any questions your group has.
-
(gdb) info locals -
(gdb) info args -
(gdb) print VALUE (or p VALUE)You can print any variable or expression, e.g. -
print x,p arr[5],p ((x & 0b1111) << 3) -
You can also specify a format to print in
-
print/t(binary),print/x(hex),print/d(decimal) -
(gdb) x ADDRESSThis prints out memory at an address, e.g. strings / arrays / pointers -
(gdb) x/16cb str1This prints the first 16 bytes ofstr1as characters -
(gdb) x/20xb str2This prints 20 bytes ofstr2in hex -
(gdb) x/4dw arrThis prints 4 “words” (i.e.int32s) ofarr, as decimal numbers -
You can use the following reference card for reference on gdb commands, and format commands for x and print.
Write your method for solving this problem on your whiteboard. Get checked off by a staff member.
Also make sure to add your comment to gradebook/comment.txt to be graded on gradescope
What the Shell?
The other day, I was working on a class assignment that had me running a bunch of stress test diagnostics for a cloud system. Each test took about a minute to run, and I had to run a bunch of these.
One of my partners asked “why not write a shell script?” And so I did. What would have been twenty-five times of typing the same command with different numbers turned into a single script I could run once and then go about my day. Now, that script probably took more than 25 minutes to write, but that’s beside the point.
Today, you will use shell scripting to organize a messy file system.
Next, change into the minihome directory
and take a look at its contents. This directory structure should hopefully look
familiar to you!
Before we get started though, let’s talk about shell scripting and the executable bit.
A shell script, as its name suggests, is a script that runs a series of shell commands that accomplishes some tasks. These scripts can get very complicated depending on the task being automated, but even simple shell scripts can save lots of time. In the coming weeks, you may want to write a shell script that runs all the tests in PA 3, for example.
Task 0: Run a script
💡 KEY POINT: Any command that you can run on the command line can be an instruction in a shell script.
- Fill the provided
task_1.shfile with some commands that you know likeecho,ls, orpwd. Each command should be on a new line. - To mark the file as executable, run
chmod +x task_1.sh. - Try running
./task_1.shin your command line, and you should see the output of each command in the order you added them to the shell script.
The #!/bin/bash at the top specifies that this script should be parsed using
the bash program at the directory /bin/. The leading #! is called a
“shebang” and signals the start of this directive. A Python script, for example,
could have #!/usr/bin/python3 as its first line instead.
Here’s an example you can try. Put the following content in task_1.sh:
#!/bin/bash

echo "Hello!"
echo "Goodbye!"
And then, run it. If you see Permission denied and don’t know what to do, go read the executable bit section from lab 2.
$ ./task_1.sh
Hello!
Goodbye!
As it turns out, all that is needed to complete the above task is to run a couple of commands sequentially. Here are a couple of knowledge bits that could be helpful:
The wildcard pattern *
In shell scripting, the * character acts as a way to target all files and directories. For example, if you ran cat *, you would print out the contents of all the files in your current working directory (you would likely also get error messages from trying to view the contents of folders in your directory). Furthermore, the * character can also be used to match specific patterns. For example, if you ran cat *.txt, you would print out the contents of all the files in your working directory that have the .txt extension.
The mv command
The move command, as its name suggests, can be used to move files into directories. For example, you can use it like so:
mv a.txt Books
This will move a.txt into the Books directory. You can also move multiple files at once like so: mv a.txt b.txt Books, which will move a.txt and b.txt into the Books directory.
Task 1: Books and Music
With these tidbits, you are now ready to write your (possibly) first ever shell script! Your first task will be to write a shell script to organize the text and mp3 files in minihome into the Books and Music directories. Please work on this with your groupmates if you so wish. As a reminder, you can use the ls -R command you all discovered back in lab 1 to test if your files ended up in the right place. While testing your script, you may end up accidentally messing up your directory structure. If this happens, we have provided you with a reset_task_1.sh script in the minihome directory which you can run to reset the .txt and .mp3 files. This will leave your .sh files intact, however, so don’t worry about losing your progress.
Our minihome is now looking a lot cleaner. But maybe we can go further. The length of these books seems a bit varied, no? It would be nice if we were able to sort these books into short stories and novels. This will be your next task. One requirement for your script is that you should be able to supply an argument for the cutoff between a novel and a short story. Before you begin the task, first change into the Books directory.
Here are some knowledge bits that could be useful:
Shell scripting - variables
You can declare and use variables like so in shell scripting:
# Contents of demo.sh
#!/bin/bash
num=5
fruit="apples"
echo $num $fruit
$ ./demo.sh
5 apples
To reference a variable, you simply put a dollar sign in front of it.
Note that this still works inside double-quoted strings, so echo "$num $fruit" would have achieved the same effect in the script above. To print out $num $fruit literally, you would need to either use single quotes ('$num $fruit') or escape the dollar signs ("\$num \$fruit").
Shell scripting - accessing command line arguments
To access the nth command line argument, use $n in your script. For example, the 1st command line argument would be accessed with $1. Note that the 0th command line argument is the name of the command you executed. Here is a demonstration:
# Contents of demo.sh
#!/bin/bash
echo $1 $2
$ ./demo.sh 5 apples and more
5 apples
Note that a string wrapped in quotes counts as one argument. For example, in: $ ./demo.sh 2 "PA 2" We have $1 equal to 2 and $2 equal to PA 2.
Shell scripting - if statements
The basic structure of an if statement in shell scripting is as follows:
if [ condition ]; then
    # Commands if condition is true
else
    # Commands if condition is false
fi
Here is an example of a script that takes in a number from the user, and prints out whether or not it is greater than 5:
# Contents of demo.sh
if [ $1 -gt 5 ]; then
    echo "Number is greater than 5"
else
    echo "Number is 5 or less"
fi
$ ./demo.sh 10
Number is greater than 5
As you can see, most operators (save for string equality) in bash scripts are different from what you would see in most other programming languages; they look like a hyphen followed by an mnemonic string. Here, the -gt comparison operator checks if $1 is greater than 5. Though you likely won’t need them for this task, here is a decently comprehensive list of the different types of conditional operators you can find in shell scripting:
File/directory existence:
if [ -f filename ]; then   # Check if file exists
if [ -d directory ]; then  # Check if directory exists
if [ -e filename ]; then   # Check if file or directory exists
if [ -s filename ]; then   # Check if file exists and is not empty
if [ -x filename ]; then   # Check if file is executable
String comparison:
if [ "$str1" = "$str2" ]; then   # Strings are equal
if [ "$str1" != "$str2" ]; then  # Strings are not equal
if [ -z "$str1" ]; then          # String is empty
if [ -n "$str1" ]; then          # String is not empty
Numerical comparison:
if [ "$num1" -eq "$num2" ]; then   # Numbers are equal
if [ "$num1" -ne "$num2" ]; then   # Numbers are not equal
if [ "$num1" -gt "$num2" ]; then   # num1 is greater than num2
if [ "$num1" -lt "$num2" ]; then   # num1 is less than num2
if [ "$num1" -ge "$num2" ]; then   # num1 is greater than or equal to num2
if [ "$num1" -le "$num2" ]; then   # num1 is less than or equal to num2
Shell scripting - for loops
In Bash, there are many different types of loops, each having their use cases. Here, we’ll introduce one of those loops: the for loop. The basic syntax is as follows:
for item in [list of items]; do
  # do something with $item
done
Here are some examples of how you can use a for loop:
-
Looping through variables:
for var in item1 item2 item3; do echo "$var" done -
Looping through a range of numbers:
for i in {1..5}; do echo "Number: $i" done -
Looping through files in a directory:
for file in *.txt; do
  echo "Processing $file"
done
The wc command
Here, wc does not stand for water closet, but rather word count. Passing it a text file will print out the number of lines, words, and characters in that file followed by the name of that file. For example:
$ wc alice.txt
3757  29564 174357 alice.txt
To print out just the number of lines, words, and characters, You can use the -l, -w, and -c options respectively:
$ wc -l alice.txt
3757 alice.txt
$ wc -w alice.txt
29564 alice.txt
$ wc -c alice.txt
174357 alice.txt
If you don’t want the name of the file after, and only wanted the number for whatever reason, you can redirect the contents of the file in to the wc command like so:
$ wc < alice.txt
3757  29564 174357
$ wc -l < alice.txt
3757
Neat!
Shell scripting - command substitution
You can run a command and assign its output (as a string) to a variable using var=$(command). For example:
lines=$(wc -l < sample.txt)
echo $lines
This would store the number of lines in sample.txt into lines and print it.
Task 2: Novels and Short Stories
With the above knowledge, you can now write a script to sort text files into the Novels and Short_Stories folder based on their word length from scratch. In task_2.sh, we have provided you a base script to work off of, with blanks for you to fill. There is also a reset_task_2.sh script, should you wish to restart. To test if your script works, 20000 works well as an argument for differentiating between Novels and Short Stories. Good luck, and have fun!
Once you have made sure that both of your scripts work, we may now proceed to the fun part. First change back to the minihome directory, run the reset_task_3.sh script to undo the changes from both task 1 and task 2. Next, run the task_3.sh script. This is a pre-written script that will run your tasks 1 and 2 in succession. This means that in one command, you can sort all of your files into Books, Novels, Short_Stories, and Music folders!
Confirm that all the text files are in the Novel folder (we used a lower threshold), and all the mp3 files are in the Music folder, and run the reset_task_3.sh script. Make sure your script works before running the next step!
Let’s pretend our user has done a lot of internet browsing and downloaded a lot of files. Run the simulate_downloads.sh script.
That’s a lot of txt and mp3 files! Normally it would take quite a while to sort these out, but luckily, we have our script! Run task_3.sh, and hopefully you should see all of the files get sorted. What normally would have taken perhaps an hour can now be done in an instant!
Please submit your gradebook/comment.txt, minihome/task_1.sh and minihome/Books/task_2.sh to gradescope.
As you continue to use vim, you may want to consider tools to enhance your experience. Below are several options:
Vundle – a plugin manager for vim https://github.com/vundlevim/vundle.vim
vimawesome – a site with plugins you can add with the help of vundle https://vimawesome.com/
These would take longer to customize so feel free to take a few minutes to look through these but do continue on without much delay.
PA1 - UTF-8: Due Monday 10/12
Representing text is straightforward using ASCII: one byte per character fits well within char[] and it represents most English text. However, there are many more than 256 characters in the text we use, from non-Latin alphabets (Cyrillic, Arabic, and Chinese character sets, etc.) to emojis and other symbols like €, to accented characters like é and ü.
The UTF-8 encoding is the default encoding of text in the majority of software today. If you’ve opened a web page, read a text message, or sent an email in the past 15 years that had any special characters, the text was probably UTF-8 encoded.

Not all software handles UTF-8 correctly! For example, Joe got a marketing email recently with a header “Take your notes further with Connect​” We’re guessing that was supposed to be an ellipsis (…), UTF-8 encoded as the three bytes 0x11100010 0x10000000 0x10100110, and likely the software used to author the email mishandled the encoding and treated it as three extended ASCII characters.
This can cause serious problems for real people. For example, people with accented letters in their names can run into issues with sign-in forms (check out @yournameisinvalid for some examples). People with names best written in an alphabet other than Latin can have their names mangled in official documents, and need to have a “Latinized” version of their name for business in the US. Joe had trouble writing lecture notes because LaTeX does not support UTF-8 by default.
UTF-8 bugs can and do cause security vulnerabities in products we use every day. A simple search for UTF-8 in the CVE database of security vulnerabilities turns up hundreds of results.
It’s useful to get some experience with UTF-8 so you understand how it’s supposed to work and can recognize when it doesn’t. To that end, you’ll write several functions that work with UTF-8 encoded text, and use them to analyze some example texts.
Getting Started
Step 1: Do the Prairielearn Problem Set #1
Before you start coding or doing the project, you need to do the Prairielearn: Problem Set 1. You will incrementally build your full UTF-8 analyzer by doing this problem set. Then you will put everything together you built in the Problem Set into one complete program that will analyze UTF-8 strings.
Step 2: Make your Git repository and begin coding
Visit this link to create your project Git repository: Classroom50
Note: Git is a command line tool used for managing source code that we will teach you to use in lab 2. You should commit and push all your code and changes to this repository.
Milestones, Working Process, and Definitions
The functions described below are organized into milestones; you should definitely finish the functions in a milestone set before moving onto the next.
In general, you should work one function at a time, and earlier functions may be useful in implementing later functions.
A good first task is to implement only is_ascii and the corresponding part of main needed to read input and print the result for is_ascii, and make sure you can test that. Then move onto capitalize_ascii, and so on.
You can and should save your work by using git commits (if you’re comfortable with that), or even just saving copies of your .c file when you hit important milestones. We may ask to see your work from an earlier milestone if you ask us for help on a function from a later one.
Some reminders and information about the function signatures:
- Your functions must have exactly the names and signatures shown below; we will test each of them individually. Incorrect function headers will lead to failed tests.
int8_tandint32_tare 8-bit (1-byte) and 32-bit (4-byte) integers. You can think ofint32_tlikeintin Java, we just want to be explicit about sizes of things when we program in C, andintcan mean different things on different systems. These types are defined instdint.h, so#include <stdint.h>at the top of a program will make them usable.- Some functions take a code point index (which character, counting from 0) and some take a byte index (which byte in the
char[], counting from 0). For ASCII text these are the same, but for other text they are not! Pay attention to which one each function takes.
Functions - Milestone 1
int8_t is_ascii(char string[])
Takes a UTF-8 encoded string and returns if it is valid ASCII (e.g. all bytes are 127 or less). The empty string is valid ASCII.
Example Usage:
printf("Is 🔥 ASCII? %d\n", is_ascii("🔥"));

=== Output ===
Is 🔥 ASCII? 0

printf("Is abcd ASCII? %d\n", is_ascii("abcd"));

=== Output ===
Is abcd ASCII? 1
int32_t capitalize_ascii(char str[])
Takes a UTF-8 encoded string and changes it in-place so that any ASCII lowercase characters a-z are changed to their uppercase versions. Leaves all other characters unchanged. It returns the number of characters updated from lowercase to uppercase.
Example Usage:
int32_t ret = 0;
char str[] = "abcd";
ret = capitalize_ascii(str);
printf("Capitalized String: %s\nCharacters updated: %d\n", str, ret);

=== Output ===
Capitalized String: ABCD
Characters updated: 4
Functions - Milestone 2
int8_t codepoint_size(char string[])
Takes a UTF-8 encoded string and returns how many bytes the first code point in it takes (start byte + continuation bytes): 1, 2, 3, or 4.
Returns 0 if the string is empty, and -1 if the first byte is not a valid start byte.
Example Usage:
printf("Size: %d bytes\n", codepoint_size("éclair")); // é is start byte 0xC3 + 1 cont. byte

=== Output ===
Size: 2 bytes

char s[] = "Héy"; // same as { 'H', 0xC3, 0xA9, 'y', 0 }
printf("Size: %d\n", codepoint_size(&s[2])); // the string starting at byte 2 starts with 0xA9, a continuation byte, not a start byte

=== Output ===
Size: -1
int32_t utf8_strlen(char str[])
Takes a UTF-8 encoded string and returns the number of UTF-8 codepoints it represents.
Returns -1 if there are any errors encountered in processing the UTF-8 string.
Example Usage:
char str[] = "Joséph";
printf("Length of string %s is %d\n", str, utf8_strlen(str));  // 6 codepoints, (even though 7 bytes)

=== Output ===
Length of string Joséph is 6
void utf8_substring(const char str[], int start, int end, char result[])
Takes a UTF-8 encoded string and start (inclusive) and end (exclusive) code point indices, and writes the substring between those indices to result, with a null terminator. Assumes that result has sufficient bytes of space available. (Hint: result will be created beforehand with a given size and passed as input here. Can any of the above functions be used to determine what the size of result should be?)
If the end index is larger than the utf8_strlen of the string, it should act as if the end index was exactly utf8_strlen of the string.
If start is negative, or start is greater than or equal to end, result should be the empty string.
Example Usage:
char str[] = "🦀🦮🦮🦀🦀🦮🦮"; // these emoji are 4 bytes long
char result[17];
utf8_substring(str, 3, 7, result);
printf("String: %s\nSubstring: %s\n", str, result);

=== Output ===
String: 🦀🦮🦮🦀🦀🦮🦮
Substring: 🦀🦀🦮🦮
Functions - Milestone 3
int32_t codepoint_at(char str[], int32_t byte_index)
Takes a UTF-8 encoded string and a byte index, and returns a decimal representing the codepoint of the character that starts at that byte.
Returns -1 if the byte at that index is not a valid start byte (for example, if it is a continuation byte) or is past the end of the string.
Example Usage:
char str[] = "Joséph"; // J o s é é p h
                       // 0 1 2 3 4 5 6  <- byte indices; é takes bytes 3 and 4
printf("Codepoint at byte 5 in %s is %d\n", str, codepoint_at(str, 5)); // 'p' starts at byte 5
printf("Codepoint at byte 3 in %s is %d\n", str, codepoint_at(str, 3)); // 'é' starts at byte 3
printf("Codepoint at byte 4 in %s is %d\n", str, codepoint_at(str, 4)); // byte 4 is the middle of 'é'

=== Output ===
Codepoint at byte 5 in Joséph is 112
Codepoint at byte 3 in Joséph is 233
Codepoint at byte 4 in Joséph is -1
int is_animal_emoji_at(const char str[], int index)
Takes a UTF-8 encoded string and a code point index, and returns 1 if the code point at that index is an animal emoji, and 0 otherwise (including if the index is out of range).
For simplicity for this question, we will define that that the “animal emojii” are in two ranges: from 🐀 to 🐿️ and from 🦀 to 🦮. (Yes, this technically includes things like 🐽 which are only related to or part of an animal, and excludes a few things like 🙊, 😸, which are animal faces.). You may find the wikipedia page on Unicode emoji helpful here.
Example Usage:
char str[] = "I 🐶 you";
printf("%d %d\n", is_animal_emoji_at(str, 2), is_animal_emoji_at(str, 0)); // 🐶 is code point 2

=== Output ===
1 0
UTF-8 Analyzer
You’ll also write a program that reads UTF-8 input and prints out some information about it.
Here’s what the output of a sample run of your program should look like:
$ ./utf8analyzer
Enter a UTF-8 encoded string: My 🐩’s name is Erdős.
Valid ASCII: false
Uppercased ASCII: "MY 🐩’S NAME IS ERDőS."
Length in bytes: 27
Number of code points: 21
Bytes per code point: 1 1 1 4 3 1 1 1 1 1 1 1 1 1 1 1 1 1 2 1 1
Substring of the first 6 code points: "My 🐩’s"
Code points as decimal numbers: 77 121 32 128041 8217 115 32 110 97 109 101 32 105 115 32 69 114 100 337 115 46
Animal emojis: 🐩
You can also test the contents of files by using the < operator:
$ cat utf8test.txt
My 🐩’s name is Erdős.
$ ./utf8analyzer < utf8test.txt
Enter a UTF-8 encoded string:
Valid ASCII: false
Uppercased ASCII: "MY 🐩’S NAME IS ERDőS."
Length in bytes: 27
Number of code points: 21
Bytes per code point: 1 1 1 4 3 1 1 1 1 1 1 1 1 1 1 1 1 1 2 1 1
Substring of the first 6 code points: "My 🐩’s"
Code points as decimal numbers: 77 121 32 128041 8217 115 32 110 97 109 101 32 105 115 32 69 114 100 337 115 46
Animal emojis: 🐩
Testing
We provide 3 basic tests in the tests folder of your Classroom50 repository. These contain simple tests for identifying valid ASCII and converting ASCII lowercase characters to uppercase.
You can see the result for a single test by using:
./utf8analyzer < tests/utf8test.txt
Here are some other ideas for tests you should write. They aren’t necessarily comprehensive (you should design your own!) but they should get you started. For each of these kinds of strings, you should check how UTF-8 analyzer handles them:
- Strings with a single UTF-8 character that is 1, 2, 3, 4 bytes
- Strings with two UTF-8 characters in all combinations of 1/2/3/4 bytes. (e.g.
"aa","aá","áa","áá", and so on) - Strings with and without animal emojii, including at the beginning, middle, and end of the string, and at the beginning, middle, and end of the range
- Strings of exactly 5 characters
We recommend saving your input in files in the tests folder and using redirection (<) to test, so you don’t have to figure out how to type the same UTF-8 characters over and over. Commit and push these test files to your repository along with your code.
Design Questions
The design questions are submitted separately from your code.
Answer each of these with a few sentences or paragraphs; don’t write a whole essay, but use good writing practice to communicate the essence of the idea. A good response doesn’t need to be long, but it needs to have attention to detail and be clear. Examples help!
Question 1
Consider these two bytes: 11000001 10000001
Based on the definition of UTF-8 we used in PA1, what code point does it encode? What are 1-byte, 3-byte, and 4-byte encodings of the same code point? Which of these are valid UTF-8 encodings of this code point? Why are they valid or not valid? (This requires some outside research – “valid” is a technical term here)
Describe how you would write a function that detects if a UTF-8 string has any invalid code points like these.
Question 2
Consider a comparison of UTF-8 with the alternate encoding UTF-32.
For a string s that is n+1 bytes long (n bytes of data with a 1-byte null terminator), strlen(s) must be equal to n.
- Is this property true for UTF-8? Explain why or give a counterexample.
- Is this property true for UTF-32? Explain why or give a counterexample.
For a string s that is n+1 bytes long (n bytes of data with a 1-byte null terminator) with the n bytes encoding 2c code points (that is, it is even length in terms of unicode characters), there is a valid code point starting at byte s[n / 2].
- Is this property true for UTF-8? Explain why or give a counterexample.
- Is this property true for UTF-32? Explain why or give a counterexample.
HINT: Write out the UTF-8 and UTF-32 encoding of a few short strings, including characters in the ASCII range and outside it.
Resources and Policy
Refer to the policies on assignments for working with others or appropriate use of tools like ChatGPT or Github Copilot.
You can use any code from class, lab, or discussion in your work.
What to Hand In
PA1 has two separate Gradescope submissions. You must complete both.
1. Code: the Project 1 - Code assignment on Gradescope
Your submission should contain:
- Any
.cfiles you wrote (can be one file or many; it’s totally reasonable to only have one). We will rungcc *.c -o utf8analyzerto compile your code, so you should make sure it works when we do that. - Your tests in files
tests/*.txt
To submit:
- Make sure all of your work is committed and pushed to your Classroom50 repository (
git statusshould show nothing left to commit, and your latest changes should be visible on GitHub). - Open the
Project 1 - Codeassignment on Gradescope and choose GitHub as the submission method. (The first time, you will need to connect your GitHub account to Gradescope.) - Select your repository,
ucsd-cse29-fall2026/cse29-fa26-pa1-<your GitHub username>, and themainbranch, then upload.
If your repository doesn’t appear in the list on Gradescope, choose Upload instead and upload your .c files and your tests folder.
Pushing to your repository does not submit your assignment, even if Classroom50 shows the assignment as Submitted. Only what you submit on Gradescope before the deadline will be graded, so if you push more changes, submit again on Gradescope.
The submission system will show you the output of compiling and running your program on the provided tests to make sure the baseline format of your submission works. You will not get feedback about your overall grade before the deadline.
2. Design Questions: the Project 1 - Design Questions assignment on Gradescope
Type your answers to the design questions directly into the Project 1 - Design Questions assignment on Gradescope. Do not put them in your repository or your code submission; answers submitted there will not be graded.
===
PA1 Resubmission: Due Date Friday 10/23 at 10:00pm
If you want to resubmit Project 1, please read this section carefully. You need to pass all the tests in the original Project 1, while also implementing an extra function described below
void next_utf8_char(char str[], int32_t cpi, char result[])
Takes a UTF-8 encoded string and a code point index. Calculates the code point at that index. Then, calculates the code point with value one higher (so e.g. for ”é“ U+00E9 that would be “ê” (U+00EA), and for “🐩” (U+1F429) that would be “🐪” (U+1F42A)). Saves the encoding of that code point in the result array starting at index 0.
Example Usage:
char str[] = "Joséph";
char result[100];
int32_t idx = 3;
next_utf8_char(str, idx, result);
printf("Next character of code point at index 3: %s\n",result);
// 'é' is the 4th codepoint represented by the bytes 0xC3 0xA9
// 'ê' in UTF-8 hex bytes is represented as 0xC3 0xAA

=== Output ===
Next character of code point at index 3: ê
Now, Your final output on running the utfanalyzer code that will be graded should contain this extra line:
Next character of code point at index 3: <FILL>
Note: If the number of codepoints in the input string is less than 4, this added line would only have the prompt without any character as follows:
Next character of code point at index 3:
The complete program output for example, should look like:
$ ./utf8analyzer
Enter a UTF-8 encoded string: My 🐩’s name is Erdős.
Valid ASCII: false
Uppercased ASCII: "MY 🐩’S NAME IS ERDőS."
Length in bytes: 27
Number of code points: 21
Bytes per code point: 1 1 1 4 3 1 1 1 1 1 1 1 1 1 1 1 1 1 2 1 1
Substring of the first 6 code points: My 🐩’s
Code points as decimal numbers: 77 121 32 128041 8217 115 32 110 97 109 101 32 105 115 32 69 114 100 337 115 46
Animal emojis: 🐩
Next character of code point at index 3: 🐪
(All our tests will check for this newly added line, in addition to lines from the original PA)
Design Question Resubmission
If you want to resubmit the design questions, we will be asking this updated design question in a new Gradescope assignment:
- UTF-8 has a leading
10on all the bytes past the first for multi-byte code points. This seems wasteful – if the encoding for 3 bytes were instead1110XXXX XXXXXXXX XXXXXXXX(whereXcan be any bit), that would fit 20 bits, which is over a million code points worth of space, removing the need for a 4-byte encoding. What are some tradeoffs or reasons the leading10might be useful? Can you think of anything that could go wrong with some programs if the encoding didn’t include this restriction on multi-byte code points?
Submission
You will resubmit your code to the Project 1 - Code Resubmission assignment on Gradescope, and the design questions to Project 1 - Design Questions Resubmission. We included a few new tests to test the functionality of your new function and utf8analyer output. You might notice that the score is out of 10,100 points, don’t worry, the new tests are not actually 1000 points each! In the spirit of masking and or’ing bits in binary, we are masking nad or’ing digits in decimal (sorta). Our threshold here remains the same. If you get 95% or above on the original Project 1 tests, and 95% or above on the new functions tests, then you will get the point for the resubmission.
PA2 - Hashing and Passwords: Due Friday 10/23 at 10:00pm
Cryptographic hash functions take an input of arbitrary length and produces a fixed length output. The special features are that the outputs are deterministic (the same input always generates the same output) and yet the outputs are apparently “random” – two similar inputs are likely to produce very different outputs, and it’s difficult to determine the input by looking at the ouput.
A common application of hashing is in storing passwords. Many systems store only the hash of a user’s password along with their username. This ensures that even if someone gains access to the stored data, users’ actual passwords are not exposed. When a user types in a password on such a system, the password handling software grants access if the hash value generated from the user’s entry matches the hash stored in the password database.
We said above that it is difficult to determine an input given an output. Password cracking is a family of techniques for accomplishing this difficult (but possible!) task. That is, let’s say we have access to a user’s password hash only. Can we figure out their password? We could then use it to log in, and it may also be shared across their accounts which we could also access.
In some cases, password cracking can exploit the structure of a hash function; this is a topic for a cryptography class. In our case, we will take a more brute-force approach: trying variations on existing known passwords, under the assumption that many passwords are easy to guess.
Getting Started
Step 1: Do Prairielearn Problem Set 2
Just like for Project 1, and all future projects, the problem set on Prairielearn is meant to help you practice the knowledge and skills you will need to use to finish this project.
Step 2: Set up Github Repository
Visit the Classroom50 assignment link. Select your username from the list (or if you don’t see it, you can skip and use your Github username). A repository will be created for you to use for your work (PLEASE MAKE SURE THE REPO HAS YOUR USERNAME IN IT). This PA should be completed on the ieng6 server. Refer to Week 1’s lab for instructions on logging in to your account on ieng6 and working with files on the server.
Note - The autograder uses the C11 standard of the C programming language.
Overall Task
We’ll start by describing the overall task and goal so it’s clear where you’re going. This may initially be very overwhelming. If it still feels difficult and unclear after you finish the problem set, it is always a good idea to try to start by outlining the problem, and breaking it down into chunks like we had you do for Project 1.
pwcrack, a Password Cracker
Write a program pwcrack that takes one command-line argument, the SHA256 hash of a password in hex format.
The program then reads from stdin potential passwords, one per line (assumed to be in UTF-8 format with only letters, no numbers or symbols).
The program should, for each password:
- Check if the SHA256 hash of the potential password matches the given hash
- Check if the SHA256 hash of the potential password with each of its ASCII characters
uppercased or lowercased matches the given hash.
- We will not check every possible combination of uppercased and lowercased letters in a password. Only versions that require a single character change like going from
passwordtoPassword
- We will not check every possible combination of uppercased and lowercased letters in a password. Only versions that require a single character change like going from
(You can use the hash.c reference file from Wednesday’s (10/14) lecture on how to use a C library to generate SHA256 hashes.)
If a matching password is found, the program should print the message below and then exit:
Found password: SHA256(<matching password>) = <hash>
If a matching password is not found, the program should print:
Did not find a matching password
Compiling Your Code
On ieng6
Because the OpenSSL libraries on ieng6 are not in the default library search path, you need to use this command:
gcc -L/usr/lib/x86_64-linux-gnu/ *.c -o pwcrack -lcrypto -lssl
The -L flag tells the compiler where to find the crypto libraries during linking.
On Other Systems
On most other Linux systems or macOS, you can compile with:
gcc *.c -o pwcrack -lcrypto
Examples
seCret has a SHA256 hash of a2c3b02cb22af83d6d1ead1d4e18d916599be7c2ef2f017169327df1f7c844fd, and notinlist
has a SHA256 hash of 21d3162352fdd45e05d052398c1ddb2ca5e9fc0a13e534f3c183f9f5b2f4a041
$ ./pwcrack a2c3b02cb22af83d6d1ead1d4e18d916599be7c2ef2f017169327df1f7c844fd
Password
NeverGuessMe!!
secret
Found password: SHA256(seCret) = a2c3b02cb22af83d6d1ead1d4e18d916599be7c2ef2f017169327df1f7c844fd
$ ./pwcrack 21d3162352fdd45e05d052398c1ddb2ca5e9fc0a13e534f3c183f9f5b2f4a041
Password
NeverGuessMe!!
secret
<Press Ctrl-D for end of input>
Did not find a matching password
We could also put the potential passwords in a file:
$ cat guesses.txt
Password
NeverGuessMe!!
secret
$ ./pwcrack a2c3b02cb22af83d6d1ead1d4e18d916599be7c2ef2f017169327df1f7c844fd < guesses.txt
Found password: SHA256(seCret) = a2c3b02cb22af83d6d1ead1d4e18d916599be7c2ef2f017169327df1f7c844fd
Note that we only consider single-character changes when trying
uppercase/lowercase variants of the guesses (i.e. we DON’T try all possible
capitalizations of the string): In the example below, the correct password is
NOT found because going from SECRET to seCret would require 5 characters to be changed.
$ ./pwcrack a2c3b02cb22af83d6d1ead1d4e18d916599be7c2ef2f017169327df1f7c844fd
SECRET
<Press Ctrl-D for end of input>
Did not find a matching password
But the correct password below WOULD be found because going from SeCret to seCret only requires one character to be changed.
$ ./pwcrack a2c3b02cb22af83d6d1ead1d4e18d916599be7c2ef2f017169327df1f7c844fd
SeCret
Found password: SHA256(seCret) = a2c3b02cb22af83d6d1ead1d4e18d916599be7c2ef2f017169327df1f7c844fd
Design Questions
Problem 1
The time command takes another command and reports how long it took to run. Use the time command on your password cracker for a password that will not match anything in the rockyou file (so it tests all of the passwords).
Show the output of the time command for your ./pwcrack on that input. Calculate (or use your program to count) the total number of times you called the SHA256 function and checked a hash against the input. How many password variants, on average, does your password cracker check per second?
Problem 2
Consider this run of your password cracker:
$ ./pwcrack 5118f76d9067edc593d6946b88693cefa6604c7e613111193db118166d4af589
apple
alpaca
backpack
Found SHA256(Backpack) = 5118f76d9067edc593d6946b88693cefa6604c7e613111193db118166d4af589
At some point in the run, your password cracker should hash and check the string alPaca .
For that moment in the program, right when your program would call SHA256 on that string:
- Copy/paste your code into your answer
- What function calls are active in your program? That is, which function is currently executing? Which function was it called from? And so on, up to main .
- For each of those function calls, what are the values of the arguments?
- For each of those function calls, what are the values of all the local variables?
What to Hand In
-
Any .c files you wrote (can be one file or many; it’s totally reasonable to only have one). Please make sure that if you turn in multiple files, that you don’t write the same function in multiple different files because that will cause the autograder to fail. You will hand in your code to the
pa2assignment on Gradescope. The autograder will give you information about if your code compiles and works on some simple examples like the ones from this writeup. -
Submit your answers to the design questions on Gradescope under the assignment
PA2 Design Questions.
Fun (and Authentic!) Testing
To help testing your PA, we are providing you with a file containing 3 million real plaintext passwords famously found a data breach of the RockYou
social network in 2009. You can use the rockyou_clean.txt password file present in the ieng6 servers by reading it into pwcrack using
the following commandline:
$./pwcrack a2c3b02cb22af83d6d1ead1d4e18d916599be7c2ef2f017169327df1f7c844fd < /home/linux/ieng6/CSE029_FA26_001/public/rockyou_clean.txt
Note: these are real human-generated passwords, so they may contain profane words (and offensive concepts). We are providing a censored version of the RockYou password list. Our filtering methodology was to remove any passwords that matched a widely-used 2,800 profane word list. If you read the contents of the password file, note that you are doing so at your own risk, as we can not guarantee that we removed all offensive passwords from the list.
Staff Passwords Scenario
You see in the news and on social media that there was a “data breach” of PrairieLearn, and the passwords of all instructors and TAs were exposed on the “dark web”. A classmate sends you a mysterious link that clearly contains usernames for the CSE29 staff and gibberish after each name.
You can find the staff password file at /home/linux/ieng6/CSE029_FA26_001/public/passwd in ieng6.
Can you figure out the passwords of each of the staff members using your pwcrack program, the data at that link, and the rockyou dataset shared above?
Cracking these is ungraded, and just provided for fun and to get your attention with a provocative scenario where password cracking would be interesting (if unethical). They aren’t our real passwords.
It also gives us a moment to discuss something important: just because you can crack passwords doesn’t mean you should. There are plenty of laws prohibiting the use of passwords that aren’t yours to access data that isn’t yours, regardless of how you obtained the password. Responsibility and ethics are another – it may simply be wrong to reverse-engineer (access to) someone else’s private data, even if it happens to be legal. Of course, there are good uses for doing this – cracking can recover a lost password needed for access to critical data, for example, if the hash is available. Like any powerful tool, your knowledge of C programming and passwords should be used with care and appropriately in context!
In many cases, finding and reporting security issues is possible to do responsibly – there’s an entire theory and practice of responsible disclosure. Researchers like Professor Aaron Schulman do work on responsibly informing companies, governments, and the public about vulnerabilities in real-world systems. So it’s critical to learn about how systems work, how secure systems fail, and how to navigate the surrounding ethical, legal, and social issues!
Resources and Policy
Refer to the policies on assignments for working with others or appropriate use of tools like ChatGPT or Github Copilot.
You can use any code from class, lab, or discussion in your work.
PA2 - Hashing and Passwords: Resubmission Due 11/6 at 10:00pm
If you want to resubmit PA2, please read this section carefully. You need to pass all the tests in the original PA2, while also implementing an extra functionality.
Implement pwcrack as originally described in the write up. Also update pwcrack to check if the SHA256 hash of the potential password with each of its numeric digits '0'-'9' replaced by all possible numberic digits '0'-'9' (considering only single digit changes) matches the given hash.
As before, only one character change at a time is tested, so if Secret111 is a potential password:
- This does NOT check
secret101as it would combine changing the case of a character and replacing a digit SeCreT111is NOT a valid variation to check as it modifies the case of two characters at the same timeSecret123is NOT a valid variation to check as it modifies two digits at the same timesecret111,Secret112,SecreT111, etc. are some valid variations to hash and check for a match
For example,
Secret112 has a SHA256 hash of b54051d1abdba8656126f85f96d9270283d34b1cb8787b78c50646d9eb4a502d
$ ./pwcrack b54051d1abdba8656126f85f96d9270283d34b1cb8787b78c50646d9eb4a502d
NeverGuessMe!!
Secret
Secret111
Found password: SHA256(Secret112) = b54051d1abdba8656126f85f96d9270283d34b1cb8787b78c50646d9eb4a502d
$ ./pwcrack b54051d1abdba8656126f85f96d9270283d34b1cb8787b78c50646d9eb4a502d
NeverGuessMe!!
secret
secret222
<Press Ctrl-D for end of input>
Did not find a matching password
Design Question Resubmission
If you want to resubmit the design questions, we will be asking this updated design question in a new Gradescope assignment:
Consider the following run of an updated pwcrack that follows the new requirements:
$ ./pwcrack b54051d1abdba8656126f85f96d9270283d34b1cb8787b78c50646d9eb4a502d
secret118
secret111
<Press Ctrl-D for end of input>
Did not find a matching password
Assume that it processes each potential password without any optimizations and does not store information from previous passwords it has checked. Answer the following questions:
- How many password variations were hashed and tested for a match?
- How many duplicate password variations were hashed and checked?
- What are ways you might change the implementation to avoid this repeated and redundant work?
Submission
When you have completed the parts that you want to resubmit, go to Gradescope and find the corresponding assignment and submit your corrected work, and the new work you have done.
PA3 - The Sea(C) Shell: Due Friday, 11/06 at 10:00pm - Classroom50 Link
Learning Goals
This assignment calls upon many of the concepts that you have practiced in previous PAs. Specifically, we will practice the following concepts in C:
- string manipulation,
- command line arguments,
- process management using fork(), exec(), wait(), and waitpid(), and of course,
- using the terminal and vim.
We’ll also get practice with a new set of functions for opening, reading from, and writing to files.
Introduction
Throughout this quarter, you have been interacting with the ieng6 server via the terminal – you’ve used vim to write code, used gcc and make to compile, used git to commit and push your changes, etc. At the heart of all this lies the shell, which acts as the user interface for the operating system.
At its core, the shell is a program that reads and parses user input, and runs built-in commands (such as cd) or executable programs (such as ls, gcc, make, or vim).
You will now create your own shell (a massively simplified one of course). We shall call it– (drumroll please)
The Sea Shell
The SEA SHell, or as we endearingly call it, seash (a name with such elegance as other popular programs in the UNIX world, e.g., git).
Getting Started
Click on the following link to accept the Classroom50 assignment: https://classroom50.org/ucsd-cse29-fall2026/cse29-fa26/assignments/pa3/accept
Overall Task
Interactive Mode
Your basic shell simply runs on an infinite loop; it repeatedly:
- prints out a prompt,
- reads keyboard input from the user
- parses the input into a command and argument list
- if the input is a built-in shell command, then executes the command directly
- otherwise, creates a child process to run the program specified in the input command, and waits for that process to finish
This mode of operation is called the interactive mode.
Batch Mode
Shell programs (like bash, which is what you have been using on ieng6) also support a batch execution mode, i.e., scripts. In this mode, instead of printing out a prompt and waiting for user input, the shell reads from a script file and executes the commands from that file one line at a time.
In both modes, once the shell hits the end-of-file marker (EOF), it should call exit(EXIT_SUCCESS) to exit gracefully. In the interactive mode, this can be done by pressing Ctrl-D.
The Prompt
In bash, you are used to seeing a prompt that looks like this:
memoryleak@ieng6-203 /current/working/dir$
You have to implement a prompt that looks like this:
you@🐚 /current/working/dir$
You don’t have to worry about the colors of the prompt(look up ANSI escape codes if you are interested but DO NOT IMPLEMENT). The prompt should be printed out every time the shell is ready to accept a new command in interactive mode. In batch mode, the prompt should not be printed.
You have to implement the prompt exactly as shown above, including the space after the $ sign. The prompt should also include the current working directory, and the username of the user running the shell. You might find the getcwd() and getpwuid() functions useful for this. (See man 3 getcwd and man 3 getpwuid.)
Parsing Input
Every time the shell reads a line of input (be it from stdin or from a file), it breaks it down into our familiar argv array.
For instance, if the user enters "ls -a -l\n" (notice the newline character), the shell should break it down into argv[0] = "ls", argv[1] = "-a", and argv[2] = "-l". You need to make sure that the argv array is NULL-terminated, i.e., argv[3] = NULL. This is important because the exec() family of functions expect a NULL-terminated array of strings.
Handling Whitespaces
You should make sure your code is robust enough to handle various sorts of whitespace characters. In this PA, we expect your shell to handle any arbitrary number of spaces ( ) and tabs (\t) between arguments.
For example, your shell should be able to handle the following input: " \tls\t\t-a -l ", and still run the ls program with the correct argv array.
strtok will be VERY helpful for this.
Built-In Commands
Whenever your shell executes a command, it should check whether the command is a built-in command or not. Specifically, the first whitespace-separated value in the user input string is the command. For example, if the user enters ls -a -l tests/, we break it down into argv[0] = "ls", argv[1] = "-a", argv[2] = "-l", and argv[3] = "tests/", and the command we are checking for is argv[0], which is "ls".
If the command is one of the following built-in commands, your shell should invoke your implementation of that built-in command.
There are three built-in commands to implement for this project: exit, cd, and history.
Built-in Command: exit
When the user types exit, your shell should call the exit system call with EXIT_SUCCESS (macro for 0). This command does not take arguments. If any is provided, the shell raises a usage error.
Built-in Command: cd
cd should be run with precisely 1 argument, which is the path to change to. You should use the chdir() system call with the argument supplied by the user. If chdir() fails (refer to man page to see how to detect failure), you should call perror("cd") to print an error message.
cd -
If the path is a hyphen (-), the shell should change back to the previous working directory, i.e., the working directory right before the most recent cd in the same shell session, and print it. (Try cd - on ieng6 to see what it does.) Don’t read the history file to figure this out. If there has been no previous cd in the session, the shell should just print the current working directory.
you@🐚 /home/you/cse29$ cd -
/home/you/cse29
you@🐚 /home/you/cse29$ cd ..
you@🐚 /home/you$ cd -
/home/you/cse29
you@🐚 /home/you/cse29$ cd -
/home/you
you@🐚 /home/you$
Built-in Command: history
When the user enters the history command with no arguments, the shell should print out the list of commands a user has ever entered in interactive mode.
(If you are on ieng6, open the ~/.bash_history file to take a look at all the commands you have executed. How far you’ve come this quarter!)
To do this, we will need to write the execution history to a file for persistent storage. Just like bash, we designate a hidden file in the user’s home directory to store the command history.
Our history file will be stored at ~/.seash_history: your home directory (getpwuid(getuid())->pw_dir) followed by /.seash_history.
Important: Every command the shell processes should be appended to the history file as one line, its arguments separated by single spaces, except:
- commands run in script mode, and
- empty commands (0 length or whitespace-only).
When the user types in the history command to our shell, it should print out all the contents of our history file, adding a counter to each line (the line number, a space, then the line):
you@🐚 /home/you/cse29$ history
1 history
you@🐚 /home/you/cse29$ pwd
/home/you/cse29
you@🐚 /home/you/cse29$ ls
pa1  pa2  pa3
you@🐚 /home/you/cse29$ history
1 history
2 pwd
3 ls
4 history
Note that the number before each line is added by history. The contents of .seash_history should not contain the leading numbers.
history -c
When the user types history -c, the shell should clear the history file, either by removing all of its contents or by deleting the file. Nothing needs to be printed.
Running Programs
If, instead, the command is not one of the aforementioned built-in commands, the shell treats it as a program, and spawns a child process to run and manage the program using the fork() and exec() family of system calls, along with waitpid() (see Waiting with waitpid() below for why wait() isn’t enough).
Running Programs in the Background
In bash, ending a command with & runs it in the background: the shell starts the program and prints the next prompt right away, without waiting for the program to finish. Your shell should do the same.
A command runs in the background if the last argument is &. For instance:
you@🐚 /home/you/cse29$ sleep 5 &
you@🐚 /home/you/cse29$
Both of these run sleep 5 in the background, and the next prompt appears immediately rather than after 5 seconds. The & is not passed to the program: sleep gets argv = {"sleep", "5", NULL}. Unlike bash, your shell doesn’t print anything when it starts a background program.
Waiting with waitpid()
Once there are background programs, wait() is no longer enough: it returns when any child process exits, which might be a background program rather than the one you just started. Use waitpid() instead (see man 2 waitpid)
For example, here the shell must wait the full 3 seconds for the second sleep, even though the background sleep 1 finishes first:
you@🐚 /home/you/cse29$ sleep 1 &
you@🐚 /home/you/cse29$ sleep 3
you@🐚 /home/you/cse29$
Policies
Your code must compile on the grader, which only has glibc.
Excluded Features
Now because our shells are quite simple, there are a lot of things that you may be accustomed to using that will not be present in our shell. (Just so you are aware how much work the authors of the bash shell put into their product!)
You will not be able to:
- use the arrow keys to navigate your command history,
- use Tab to autocomplete commands,
- use the tilde character (~) to represent your home directory,
- use redirection (> and <),
- pipe between commands (|),
- and many more…
Don’t be concerned when these things don’t work in your shell implementation!
If this were an upper-division C course, we would also ask you to implement redirection and piping.
Handling Errors
Because the shell is quite a complex program, we expect you to handle many different errors and print appropriate error messages. To make this simple, we now introduce:
Usage Errors
This only applies to built-in commands. When the user invokes one of the shell’s built-in commands, we need to check if they are doing it correctly.
- For
cd, we expectargc == 2, - For
history, we expect an optional-cargument and nothing else, - For
exit, we expectargc == 1.
If the user enters an incorrect command, e.g. exit 1, cd without a path, history -x, or history 1 2, then you should print seash: Usage error (followed by a newline) to stderr, and continue to the next iteration of the loop.
Errors to handle
You need to handle errors from the following system calls/library functions using perror(). Please pay attention to the string we give to perror() in each case and reproduce it in your code exactly.
| Error | Print (to stderr) | Then |
|---|---|---|
| Built-in command used incorrectly (see Usage Errors) | seash: Usage error | continue to the next command |
fopen(filename, ...) fails on the script file | perror(filename) | exit with status 1 |
fopen() fails on the history file | perror("open") | exit with status 1 |
chdir() fails | perror("cd") | continue to the next command |
execvp(cmd, ...) fails | perror(cmd) | exit the child with EXIT_FAILURE |
fork() fails | perror("fork") | continue to the next command |
seash run with more than one argument | Usage: ./seash [script] | exit with status 1 |
For example, running nonexistent -q should print nonexistent: No such file or directory.
The Code Base
You are given the following files:
- seash.c: Implements the shell.
Running seash
First, run gcc seash.c -o seash to compile everything. You should see the seash executable in your assignment directory.
To run seash in interactive mode (accepting keyboard input), type
$ ./seash
Or, to run a script (e.g., script.sh), type
$ ./seash script.sh
Design Questions
On ieng6 , start your shell, and from your shell, run vim . Then, in another terminal logged into the same ieng6 machine (e.g. ieng6-201, ieng6-202, ieng6-203), run ps -u . Copy-paste the output, and answer:
- Which listed process is your shell?
- Which listed process is the
bashshell that you started your shell from? - Which listed process is the
vimprocess that started from your shell? - Run
ps -au. Copy-paste the output. Make a few guesses about what you think is happening with these other processes.
What to Hand In
- Submit your code to Gradescope under the assignment
Project 3 - Code - CREDITS.txt is required (more details on the syllabus)
- We will run your program with
gcc seash.c -o seashand./seashin both interactive and batch mode - Submit a your Design Question Answers to Gradescope under the assignment
Project 3 - Design Questions
Resources and Policy
Refer to the policies on assignments for working with others or appropriate use of tools like ChatGPT or Github Copilot.
You can use any code from class, lab, or discussion in your work.